

The dataset viewer is not available for this subset.
Need help to make the dataset viewer work? Make sure to review how to configure the dataset viewer, and open a discussion for direct support.
YAML Metadata Warning:empty or missing yaml metadata in repo card
Check out the documentation for more information.
ΩFFFΣLLIα llama.cpp

Inferência de LLM em C/C++, com a interface Web construída a partir deste código.

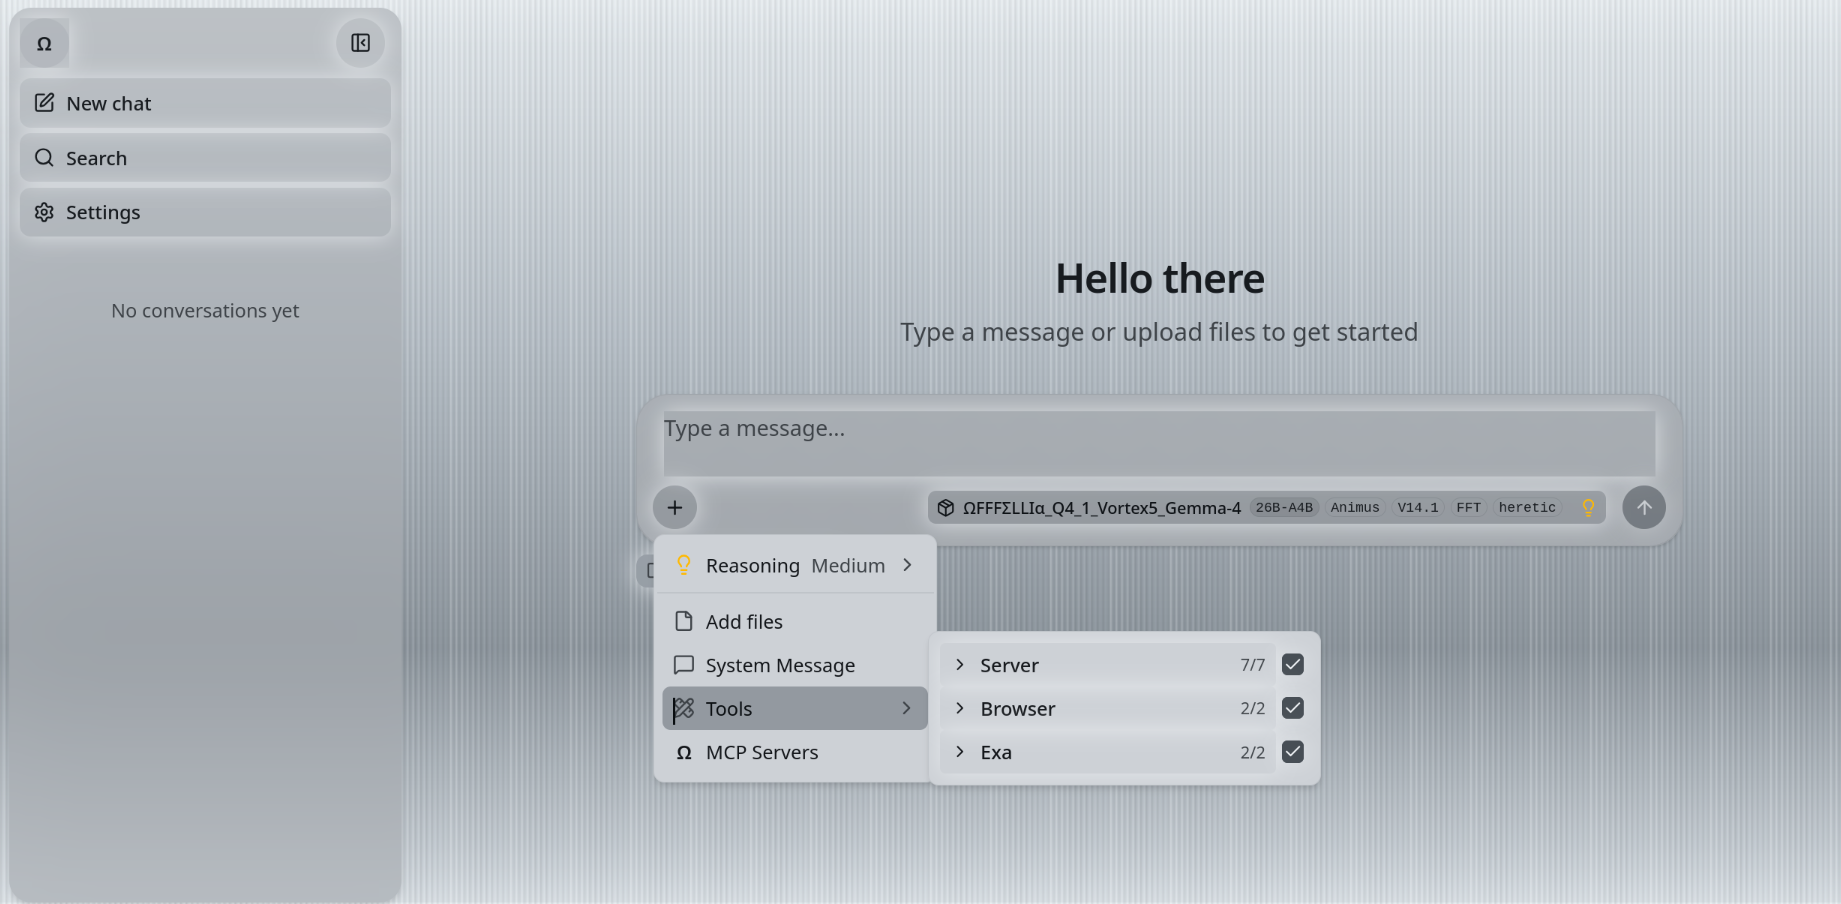
Árvore local de llama.cpp. O nome ΩFFFΣLLIα llama.cpp aparece no centro de qualquer página da interface, em qualquer porta do llama-server. Os logos SVG da interface foram substituídos pelo caractere Ω.
Modificações
| Área | Comportamento nesta árvore |
|---|---|
| Compilação | O CMake principal força LLAMA_BUILD_UI=ON e LLAMA_USE_PREBUILT_UI=OFF. Sempre que o servidor entra no build, o Vite compila tools/ui a partir do código local. Um cache antigo não reativa o download. |
| Atualização automática | A compilação não baixa dist.tar.gz nem consulta o Hugging Face. Não há checagem SHA-256 do pacote da interface. |
| PWA | O service worker não é registrado e não há aviso de versão nova. sw.js, manifest, Workbox e version.json não são exigidos para embutir a interface. |
| Favicon e SVG | npm run build é só vite build. O gerador de assets PWA não lê nem regrava favicon.svg. O HTML não declara favicon e o manifesto não lista ícones. |
| Logos | O logo da barra lateral e o logo MCP renderizam Ω no lugar do SVG. |
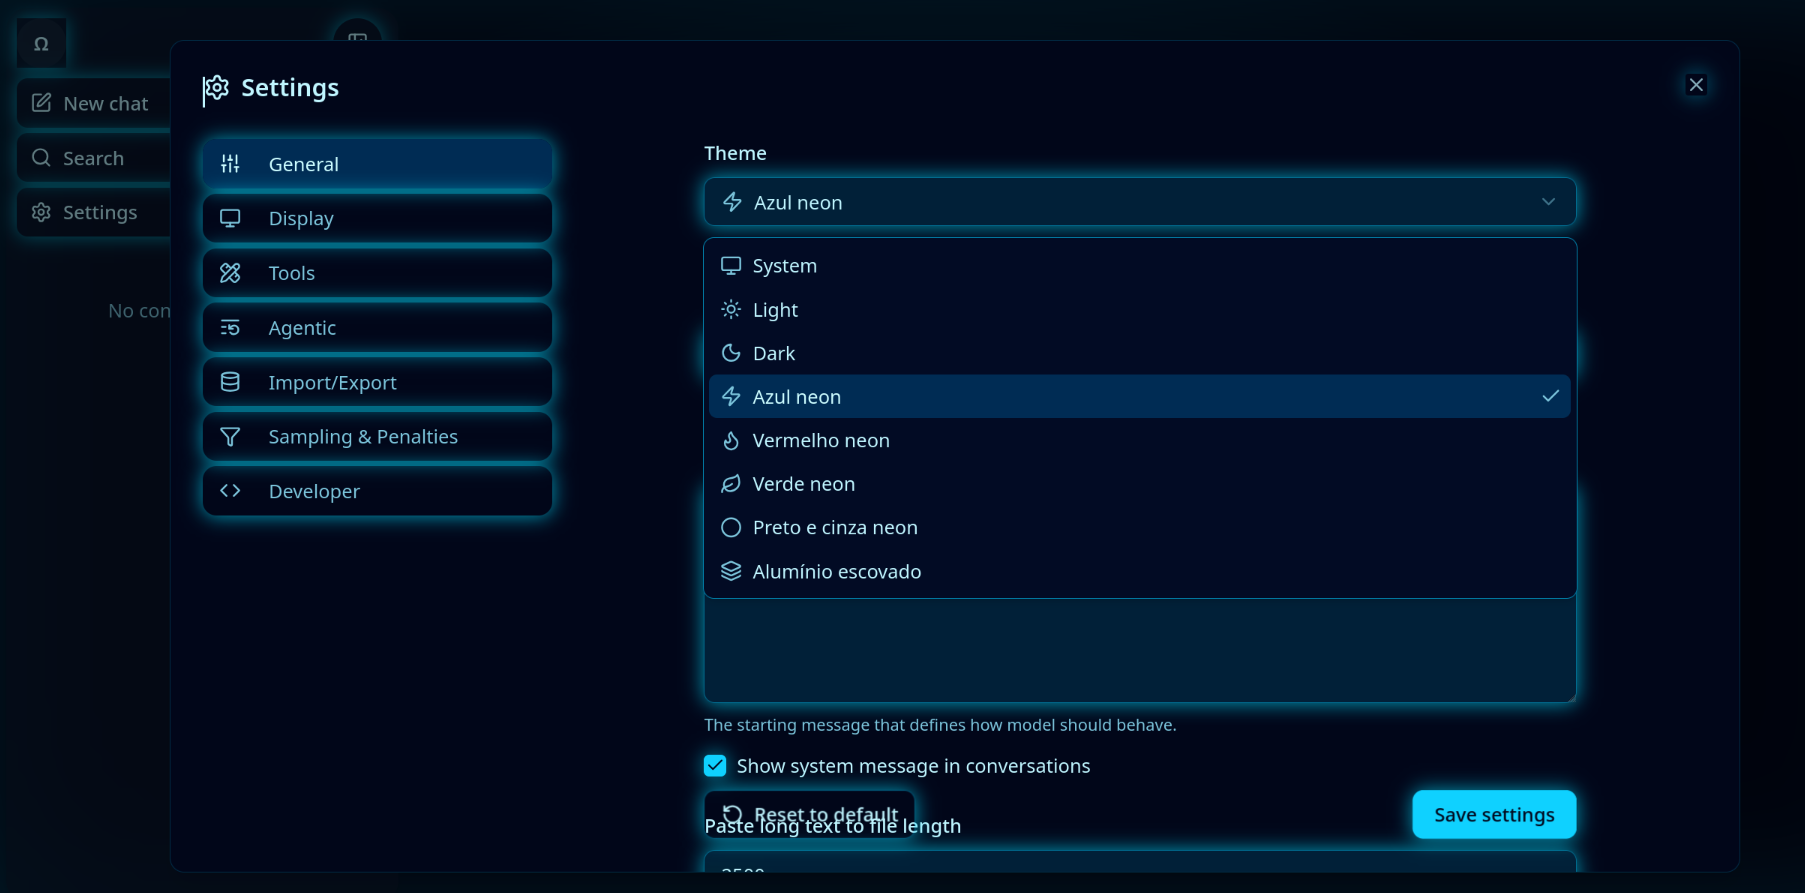
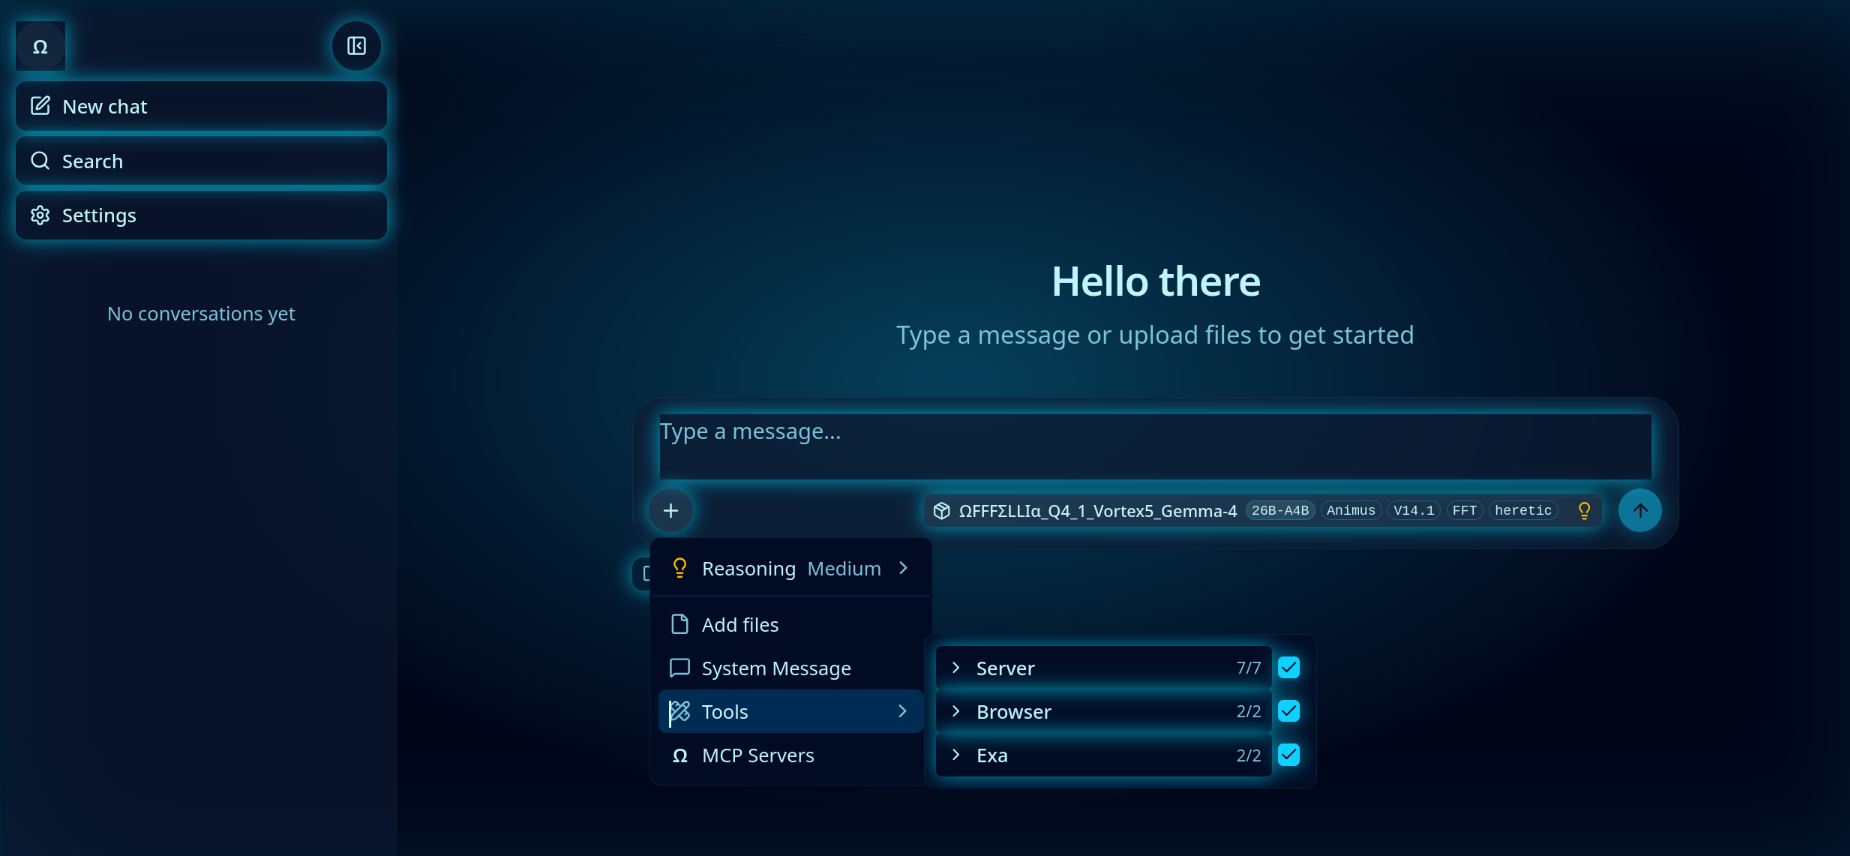
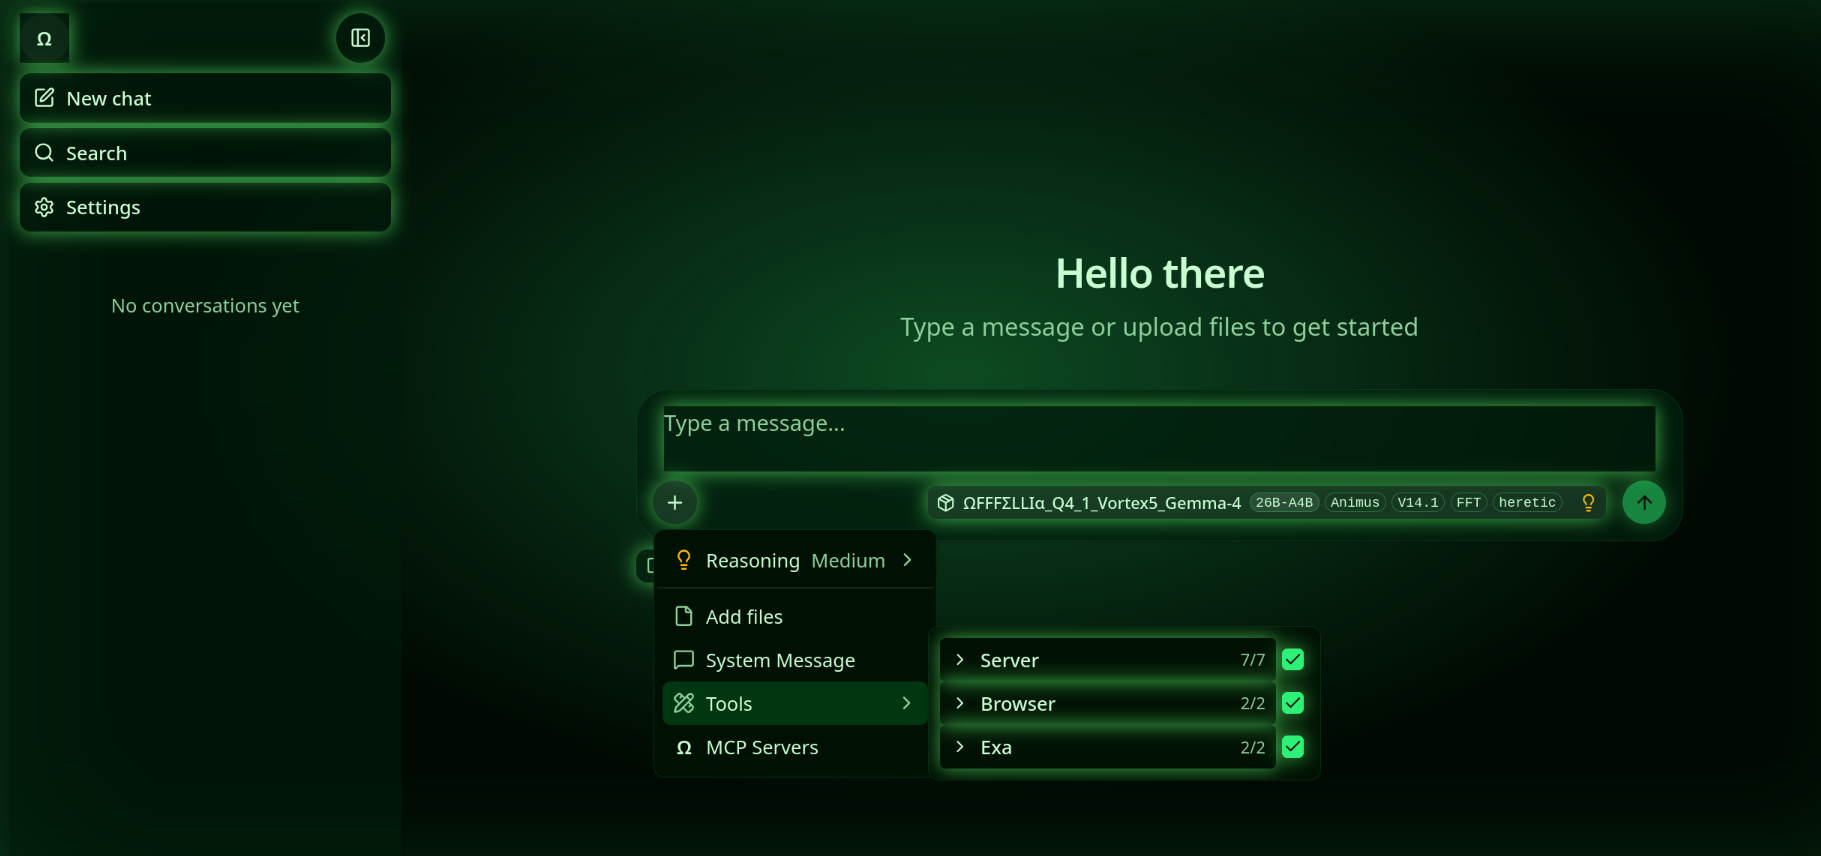
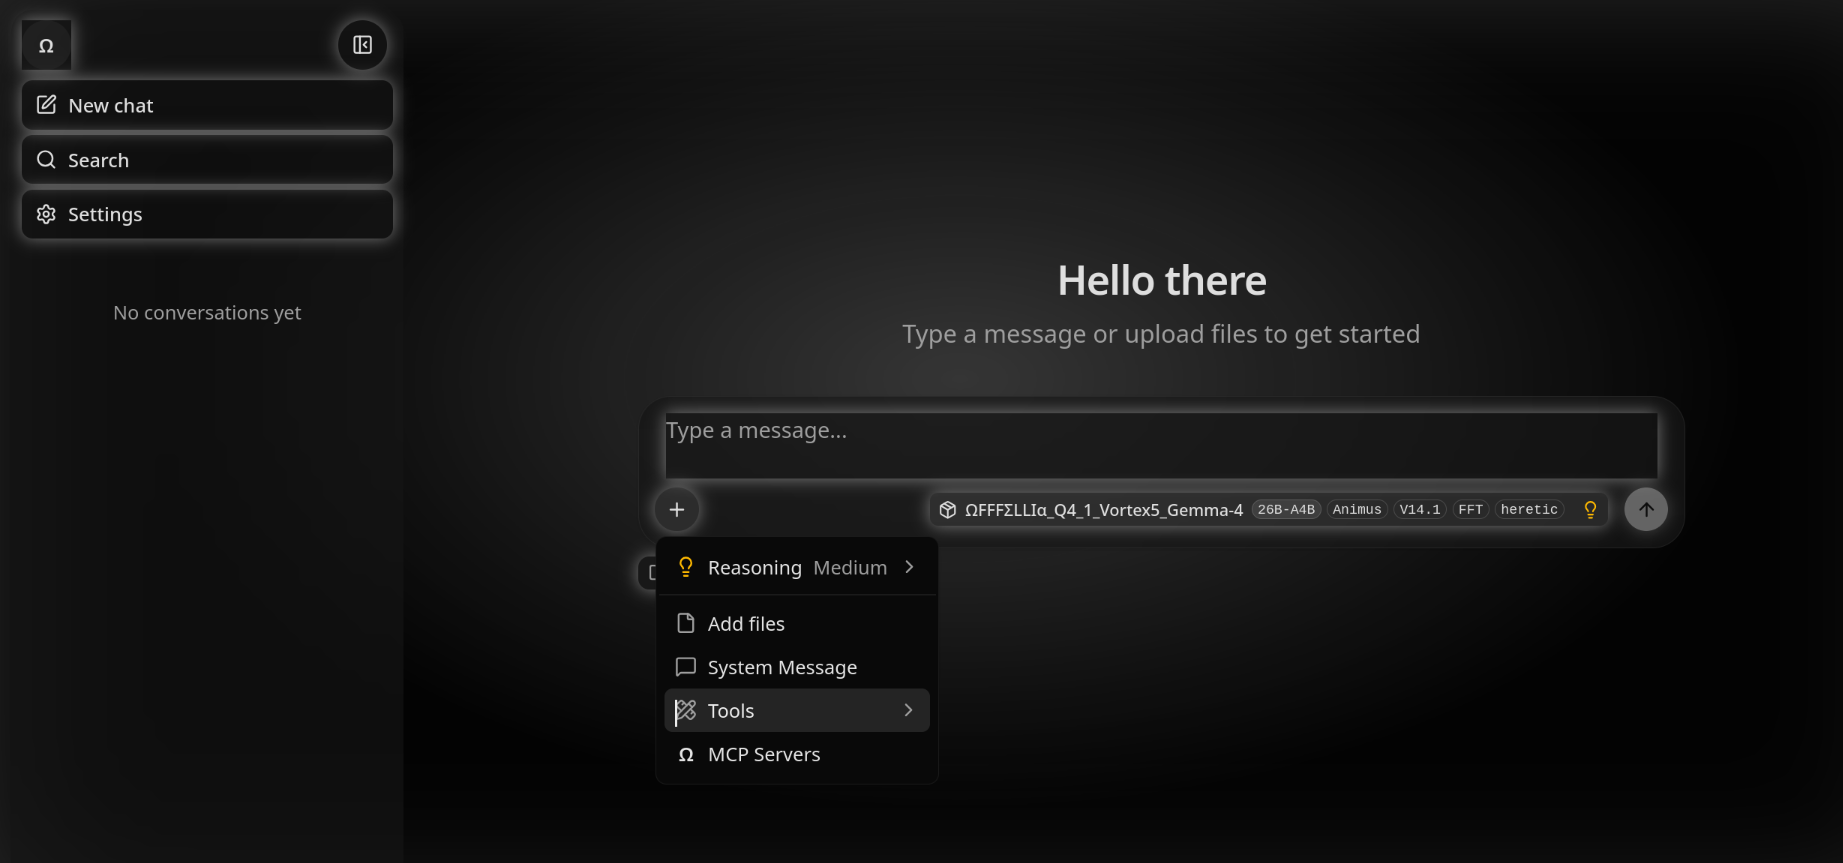
| Temas | Em Theme há cinco opções neon: Azul neon, Vermelho neon, Verde neon, Preto e cinza neon e Alumínio escovado. Cada uma troca a paleta e acende bordas, botões e o nome central. |
| MCP | O proxy CORS da interface (--ui-mcp-proxy) fica ligado por padrão. --no-ui-mcp-proxy desliga. Servidores MCP ainda pedem --mcp-servers-config ou --mcp-servers-json. As ferramentas de shell continuam desligadas sem --tools ou --agent. |
A primeira compilação do servidor precisa de Node.js e npm, porque o Vite instala as dependências da interface e gera os assets embutidos.
Não exponha o llama-server fora da máquina enquanto o proxy MCP estiver ativo.
Quick start
A few options to get llama.cpp installed on your machine:
# curl
curl -LsSf https://llama.app/install.sh | sh

# powershell
irm https://llama.app/install.ps1 | iex
- Visit https://llama.app and follow the instructions
- Run with Docker - see our Docker documentation
- Download pre-built binaries from the releases page
- Build from source by cloning this repository - check out our build guide
Once installed:
# Download and run a model directly from Hugging Face
llama cli -hf ggml-org/Qwen3.5-0.8B-GGUF

# Launch OpenAI-compatible API server
llama serve -hf ggml-org/Qwen3.5-0.8B-GGUF
|
|
|
Description
The main goal of llama.cpp is to enable LLM (and VLM) inference with minimal setup and state-of-the-art performance on
a wide range of hardware - locally and in the cloud.
- Plain C/C++ implementation without any dependencies
- Apple silicon is a first-class citizen - optimized via ARM NEON, Accelerate and Metal frameworks
- AVX, AVX2, AVX512 and AMX support for x86 architectures
- RVV, ZVFH, ZFH, ZICBOP and ZIHINTPAUSE support for RISC-V architectures
- 1.5-bit, 2-bit, 3-bit, 4-bit, 5-bit, 6-bit, and 8-bit integer quantization for faster inference and reduced memory use
- Custom CUDA kernels for running LLMs on NVIDIA GPUs (support for AMD GPUs via HIP and Moore Threads GPUs via MUSA)
- Vulkan and SYCL backend support
- CPU+GPU hybrid inference to partially accelerate models larger than the total VRAM capacity
The llama.cpp project is build on top of the ggml library.
Supported backends
| Backend | Target devices |
|---|---|
| BLAS | All |
| BLIS | All |
| CANN | Ascend NPU |
| CUDA | Nvidia GPU |
| HIP | AMD GPU |
| Hexagon | Snapdragon |
| IBM zDNN | IBM Z & LinuxONE |
| MUSA | Moore Threads GPU |
| Metal | Apple Silicon |
| OpenCL | Adreno GPU |
| OpenVINO [In Progress] | Intel CPUs, GPUs, and NPUs |
| RPC | All |
| SYCL | Intel GPU |
| VirtGPU | VirtGPU APIR |
| Vulkan | GPU |
| WebGPU | All |
| ZenDNN | AMD CPU |
Documentation
Tools
Development
- How to build
- Running on Docker
- Build on Android
- Multi-GPU usage
- Performance troubleshooting
- GGML tips & tricks
- XCFramework
- Completions
- Models
- Release process
Contributing
- Contributors can open PRs
- Collaborators will be invited based on contributions
- Maintainers can push to branches in the
llama.cpprepo and merge PRs into themasterbranch - Any help with managing issues, PRs and projects is very appreciated!
- Read the CONTRIBUTING.md for more information
Acknowledgements
- yhirose/cpp-httplib - Single-header HTTP server, used by
llama-server- MIT license - nothings/stb - Single-header image format decoder, used by multimodal subsystem - Public domain
- nlohmann/json - Single-header JSON library, used by various tools/examples - MIT License
- mackron/miniaudio - Single-header audio format decoder, used by multimodal subsystem - Public domain
- sheredom/subprocess.h - Single-header process launching solution for C and C++ - Public domain
- Downloads last month
- 64