

YOLO12L Person Segmentation
This repository contains YOLO12-large instance-segmentation models trained to detect and segment one functional class: person. PyTorch and ONNX artifacts are available for the original and extended checkpoints.
Hugging Face may display an autogenerated example that imports
YOLOvXXand callsfrom_pretrained(). That generated snippet is not valid Ultralytics Python for this repository. Use one of the tested examples below: download an exact artifact withhf_hub_download()orhf download, then load its local path withultralytics.YOLO.
Artifacts
The extended checkpoint is recommended for new use. All four model files use Git LFS.
| Artifact | Training stage | Format | Size | SHA-256 |
|---|---|---|---|---|
yolo12l-person-seg.pt |
Original 100-epoch run | PyTorch/Ultralytics | 58,148,802 bytes | abc090155cfe7a883fcc613868f482fa7db04ea67a6b4366c58c07deaa4c2ba1 |
yolo12l-person-seg-extended.pt |
Separate 300-epoch continuation stage | PyTorch/Ultralytics | 58,189,122 bytes | 7aeafb431135d431a9754f1c6c96303c41fa6b83c50587c330ec93700c72f9b0 |
onnx/yolo12l-person-seg.onnx |
Export of original checkpoint | ONNX FP32 | 115,076,428 bytes | dc238ec672ea9d1322d88cecacafba40c068653efb96dd3ea9672a97a248ecb9 |
onnx/yolo12l-person-seg-extended.onnx |
Export of extended checkpoint | ONNX FP32 | 115,076,428 bytes | 21670610cff38057d564dde39099cc7d32e6ba24e2a495607e93e4c6bd9b4800 |
The same values are machine-readable in SHA256SUMS. See
PROVENANCE.md for the training and ONNX-conversion record.
Install
Python 3.10 or newer is recommended. The checked-in requirements pin the direct user-facing packages used for the known-good inference checks. Platform and transitive dependencies such as PyTorch may vary:
python -m venv .venv
source .venv/bin/activate
python -m pip install --upgrade pip
python -m pip install -r requirements.txt
Ultralytics installs an appropriate default PyTorch dependency. GPU users who need a specific CUDA build should install PyTorch using the official PyTorch selector first, then install this repository's requirements.
Compatibility recorded during the 2026 audit:
- Checkpoints created with Ultralytics
8.3.86. - The original checkpoint loaded and inferred successfully with its creation-era Ultralytics
8.3.86; both checkpoints were tested with8.4.21; and the original checkpoint was additionally smoke-tested with8.4.126. - The contributed ONNX files were reproduced with Ultralytics
8.4.21, PyTorch2.10.0, ONNX1.20.1, onnxslim0.1.87, and ONNX Runtime1.24.3. - The copy-paste examples below use the known-good Ultralytics
8.4.21environment inrequirements.txt.
PyTorch quickstart
hf_hub_download() resolves the real Git-LFS object and caches it locally. The example pins the
artifact-bearing merge commit and verifies the checkpoint hash before invoking PyTorch; this avoids
both a moving main reference and accidentally passing a small LFS pointer file to the unpickler.
import hashlib
import cv2
from huggingface_hub import hf_hub_download
from ultralytics import YOLO

revision = "1e7437ce8625e8d0e9e220899f77f45ef70c8086"
expected_sha256 = "7aeafb431135d431a9754f1c6c96303c41fa6b83c50587c330ec93700c72f9b0"
weights = hf_hub_download(
    repo_id="RyanJames/yolo12l-person-seg",
    filename="yolo12l-person-seg-extended.pt",
    revision=revision,
)

digest = hashlib.sha256()
with open(weights, "rb") as model_file:
    for chunk in iter(lambda: model_file.read(1024 * 1024), b""):
        digest.update(chunk)
if digest.hexdigest() != expected_sha256:
    raise RuntimeError("Checkpoint SHA-256 did not match the published artifact")

model = YOLO(weights)
result = model.predict(
    "image.jpg",
    imgsz=640,
    conf=0.25,
    classes=0,
    retina_masks=True,
)[0]

# result.plot() returns a correctly sized BGR image with boxes and masks.
if not cv2.imwrite("segmented_image.jpg", result.plot()):
    raise RuntimeError("Could not write segmented_image.jpg")
retina_masks=True is important when manually combining masks with the original image: without it,
result.masks.data normally uses inference resolution rather than original-image resolution.
result.plot() is the simplest safe visualization path.
ONNX quickstart
The ONNX artifacts avoid PyTorch checkpoint reconstruction and are useful with ONNX Runtime and cross-platform deployments. Loading them through Ultralytics supplies the required preprocessing, non-maximum suppression, and segmentation-mask decoding:
import cv2
from huggingface_hub import hf_hub_download
from ultralytics import YOLO

onnx_path = hf_hub_download(
    repo_id="RyanJames/yolo12l-person-seg",
    filename="onnx/yolo12l-person-seg-extended.onnx",
    revision="1e7437ce8625e8d0e9e220899f77f45ef70c8086",
)

model = YOLO(onnx_path, task="segment")
result = model.predict(
    "image.jpg",
    imgsz=640,
    conf=0.25,
    classes=0,
    rect=False,
    retina_masks=True,
)[0]

if not cv2.imwrite("segmented_image_onnx.jpg", result.plot()):
    raise RuntimeError("Could not write segmented_image_onnx.jpg")
Use square preprocessing such as rect=False when comparing PyTorch and this static ONNX export.
Otherwise, the PyTorch path may use minimal rectangular padding while the ONNX path necessarily
receives a 640 by 640 tensor, which can change marginal detections even when the model weights are
equivalent.
ONNX interface contract
| Property | Value |
|---|---|
| Precision | FP32 |
| Input | images, float tensor [1, 3, 640, 640] |
| Prediction output | [1, 37, 8400] |
| Mask prototypes | [1, 32, 160, 160] |
| ONNX IR / opset | IR 10 / standard ai.onnx opset 22 |
| Dynamic shapes | No |
| Built-in NMS | No |
| Validated runtime | ONNX Runtime 1.24.3 |
Direct ONNX Runtime consumers must implement the same image normalization, resizing/padding, NMS, and mask decoding as Ultralytics. These approximately 110 MiB static FP32 exports are portability artifacts, not quantized mobile or edge models.
The ONNX conversions were contributed by Tom (@h43lb1t0)
in pull request #2.
They were independently reproduced from the trusted PyTorch checkpoints: all graph nodes and all
475 initializer tensors matched, and the serialized models differed only in their export timestamp.
Command-line downloads
Download the recommended PyTorch checkpoint:
hf download RyanJames/yolo12l-person-seg \
  yolo12l-person-seg-extended.pt \
  --revision 1e7437ce8625e8d0e9e220899f77f45ef70c8086 \
  --local-dir .
Download the recommended ONNX checkpoint:
hf download RyanJames/yolo12l-person-seg \
  onnx/yolo12l-person-seg-extended.onnx \
  --revision 1e7437ce8625e8d0e9e220899f77f45ef70c8086 \
  --local-dir .
If cloning with Git, install Git LFS before cloning or run git lfs pull afterwards. Verify the
downloaded files from the repository root with:
shasum -a 256 -c SHA256SUMS
Included inference program
sample_inference.py downloads the recommended artifact from the pinned artifact revision when
--model is omitted, verifies its published SHA-256, supports both formats, saves a visualization,
and always writes JSON—even when no people are detected.
# Recommended PyTorch artifact
python sample_inference.py --image image.jpg

# Recommended ONNX artifact
python sample_inference.py --image image.jpg --format onnx

# Explicit local artifact
python sample_inference.py \
  --image image.jpg \
  --model ./yolo12l-person-seg-extended.pt \
  --output result.jpg \
  --json result.json
Git-LFS troubleshooting
If loading fails with:
UnpicklingError: invalid load key, 'v'.
the file is normally a Git-LFS pointer rather than the checkpoint. A pointer starts with
version https://git-lfs.github.com/spec/v1 and is only about 130 bytes; the real PyTorch artifacts
are about 58 MB. Redownload with hf_hub_download(), hf download, or a completed git lfs pull.
The ONNX files also use Git LFS, so the same download rule applies to them.
If loading fails with an error such as:
AttributeError: 'AAttn' object has no attribute 'qk'
use the official PyPI Ultralytics package from the tested environment above. These are standard
YOLO12L checkpoints, not Turbo checkpoints: all 16 embedded AAttn blocks use qkv, not qk.
That attribute mismatch indicates an incompatible YOLOv12 fork/runtime and is unrelated to CUDA.
The materialized checkpoint-compatible architecture is
training/yolo12l-person-seg.yaml.
Model architecture and labels
The unfused 640-pixel model summary is:
- 510 layers
- 28,696,083 parameters
- Approximately 134.7 GFLOPs
- One functional class: person
The current artifacts embed the generic single-class name {0: "item"} because training used
single_cls=True. In this repository, class 0 always means person. The sample program reports
both the functional label (person) and the embedded label (item). The existing binaries have not
been silently rewritten because preserving their hashes is important for provenance. A future
metadata-normalized release should update PyTorch and ONNX together.
Training and provenance
The model was trained from the checked-in YOLO12L segmentation architecture, rather than initialized
from a pretrained .pt checkpoint, on a person-only annotation transformation of COCO:
- All 118,287 COCO
train2017images and all 5,000 COCOval2017images remained in the image directories. - 64,114 training images and 2,693 validation images had at least one person annotation.
- Only class
0person labels were written. Images without a person label were retained and treated by Ultralytics as background images. - Input size 640 by 640
- Batch size 8
classes=0andsingle_cls=Trueoverlap_mask=Trueandmask_ratio=4
The first checkpoint came from a 100-epoch run. The extended checkpoint came from a separate
300-epoch continuation stage initialized from the earlier run's last.pt. The continuation command
did not use optimizer resume; it started a fresh optimizer and schedule with lr0=0.005. It is
therefore inaccurate to describe the extended artifact as merely 200 additional epochs bringing one
continuous run to a total of 300.
The exact one-class materialized architecture and a portable description of the filtered data layout
are available under training/. Historical machine-specific dataset paths have not
been presented as current user paths.
Validation metrics
These values come from the checkpoint metadata. They were measured across all 5,000 COCO val2017
images with only person annotations retained. Of those images, 2,693 had at least one person label;
the remainder were evaluated as background images.
| Metric | Original 100-epoch checkpoint | Extended continuation checkpoint |
|---|---|---|
| Box mAP50-95 | 0.62811 | 0.64166 |
| Box mAP50 | 0.83997 | 0.85138 |
| Mask mAP50-95 | 0.52368 | 0.53725 |
| Mask mAP50 | 0.82082 | 0.83673 |
| Box precision | 0.83526 | 0.84031 |
| Box recall | 0.74425 | 0.75893 |
| Mask precision | 0.84332 | 0.84309 |
| Mask recall | 0.72293 | 0.74807 |
These are person-only metrics over the full val2017 image set, not 80-class full-COCO benchmark
scores. They should not be interpreted as a guarantee for other camera domains, demographics,
geographies, lighting conditions, resolutions, or deployment hardware.
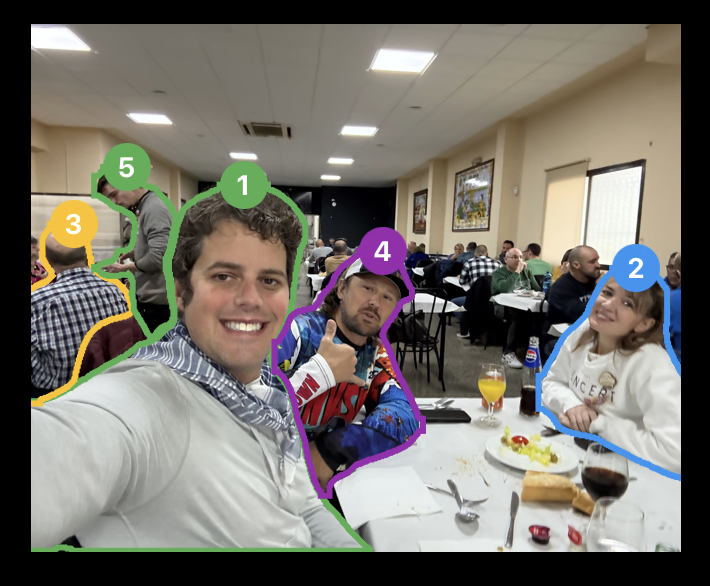
Example results
 |
 |
 |
 |

Limitations and responsible use
- The model detects a single functional class and does not identify people or infer identity, intent, age, gender, ethnicity, emotion, or other personal attributes.
- Small, distant, occluded, motion-blurred, unusually posed, or poorly lit people may be missed or incompletely segmented. False positives and inaccurate boundaries are possible.
- The person-only COCO annotation transformation does not establish equal performance across demographic groups, geographies, assistive devices, clothing, camera types, or deployment environments. Evaluate the intended domain before use.
- Do not use the model as the sole basis for consequential decisions about a person. Human review and a fit-for-purpose evaluation are required for safety-sensitive applications.
- Person detection can enable intrusive surveillance. Obtain appropriate consent, minimize retained imagery, protect derived data, restrict access, and comply with applicable privacy, biometric, employment, and surveillance law.
- The large model benefits from a GPU for low-latency workloads. The included ONNX files are static FP32 portability exports and are not optimized for phones or small edge devices.
- No throughput claim is made because speed depends on hardware, precision, image size, batching, preprocessing, postprocessing, and runtime.
License
The repository is distributed under the
GNU Affero General Public License v3.0 (AGPL-3.0). The model was built with the
Ultralytics framework; review the applicable Ultralytics licensing terms and ensure that your
application and any network deployment comply with them.
- Downloads last month
- 836