

Model card: add measured tok/s (Meridian, base, VibeThinker-3B), VibeThinker-3B comparisons in Track A/B tables, tuned VibeThinker summary; keep table edit from main
Browse files- README.md +135 -74
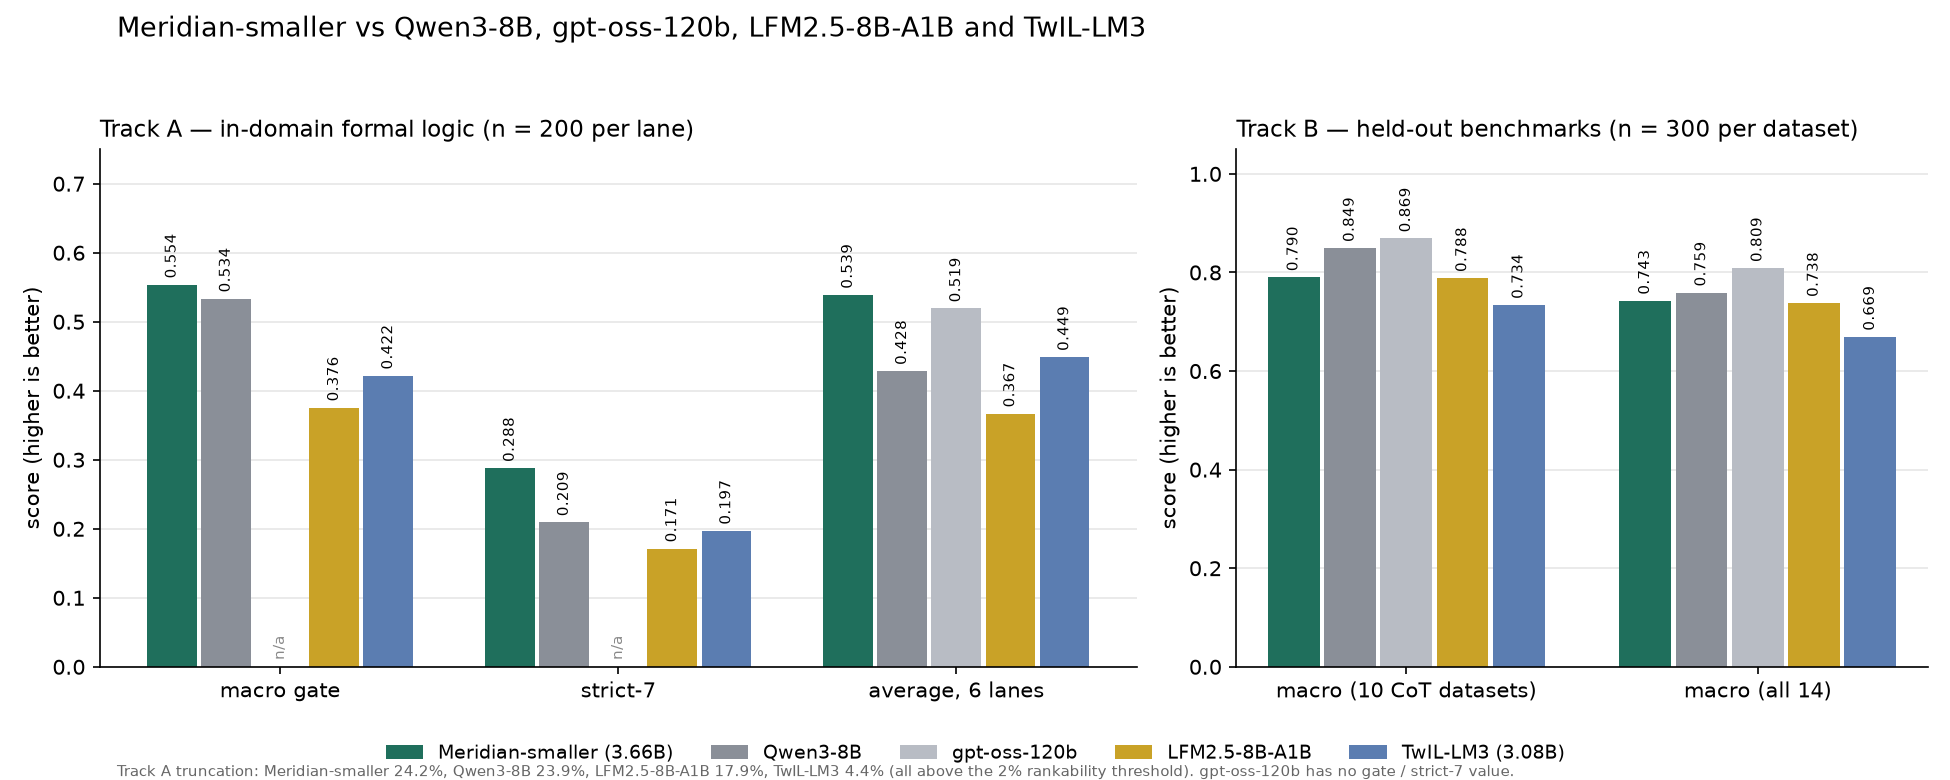
- benchmarks.png +2 -2
README.md
CHANGED
|
@@ -33,9 +33,9 @@ It improves in-domain formal-logic performance by **+28% relative** over its bas
|
|
| 33 |
macro is level with the base (0.7942 → 0.7901) and the 14-dataset macro improves slightly
|
| 34 |
(0.7332 → 0.7425). On the same harness and sampled rows it reaches the highest Track A macro
|
| 35 |
gate, strict-7 and six-lane average of any arm in the tables below for which each can be
|
| 36 |
-
computed, including Qwen3-8B and gpt-oss-120b (the 120B has no gate or strict-7 value).
|
| 37 |
|
| 38 |
-
.
|
| 67 |
|
| 68 |
## Model Details
|
|
@@ -92,30 +99,31 @@ here.
|
|
| 92 |
|
| 93 |
### Track A — in-domain formal logic
|
| 94 |
|
| 95 |
-
Meridian-smaller
|
| 96 |
-
sampled rows described under [Evaluation protocol](#evaluation-protocol), and the
|
| 97 |
-
are the values already published for TwIL-LM3 on its card, produced by that
|
| 98 |
-
[Comparability](#limitations-and-caveats)). Throughput rows
|
| 99 |
-
throughput
|
| 100 |
-
so it measures completed answers rather than raw decode rate.
|
| 101 |
-
|
| 102 |
-
|
| 103 |
-
|-
|
| 104 |
-
|
|
| 105 |
-
|
|
| 106 |
-
|
|
| 107 |
-
|
|
| 108 |
-
|
|
| 109 |
-
|
|
| 110 |
-
|
|
| 111 |
-
|
|
| 112 |
-
|
|
| 113 |
-
|
|
| 114 |
-
| **
|
| 115 |
-
|
|
| 116 |
-
|
|
| 117 |
-
|
|
| 118 |
-
|
|
|
|
|
| 119 |
|
| 120 |
‡ **gpt-oss-120b** runs MXFP4 weights at tensor-parallel 2 — quantized and multi-GPU, so its
|
| 121 |
throughput rows are not directly comparable to the single-GPU BF16 arms. Its `procedural` lane
|
|
@@ -126,11 +134,17 @@ average cannot be computed for it; that is what the — cells mean, not a zero.
|
|
| 126 |
format and tokenizer make the corpus lanes score a different quantity. The number is reported
|
| 127 |
for completeness but is not a comparable measurement, and is excluded from the bolding.
|
| 128 |
|
| 129 |
-
**Throughput
|
| 130 |
-
|
| 131 |
-
|
| 132 |
-
|
| 133 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 134 |
|
| 135 |
**`average, 6 lanes`** is the plain mean of the six objective rows above it, each at whatever
|
| 136 |
scoring that row reports (Lean F1, rule derivation, entailment, MCQ strict, semantic F1, critic).
|
|
@@ -165,6 +179,13 @@ Qwen3-8B the gate gap is only 0.020, but strict-7 is 0.2879 against 0.2093 — a
|
|
| 165 |
does not depend on loose-match credit — and Meridian-smaller leads on MCQ (strict 0.4100 against
|
| 166 |
0.0000), rule induction (0.4195 against 0.3680) and both perplexity lanes.
|
| 167 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 168 |
It does not lead every lane. gpt-oss-120b is clearly stronger on `rule_induction` (0.6518),
|
| 169 |
entailment (0.7750) and Lean formalisation (0.6306), and TwIL-LM3 remains ahead on Lean
|
| 170 |
formalisation (0.5869 against 0.5092) and semantic parsing (0.4416 against 0.4295). The two weak
|
|
@@ -173,27 +194,27 @@ spots in absolute terms are `procedural` (strict 0.1200, loose 0.2350) and FOL t
|
|
| 173 |
|
| 174 |
### Track B — held-out benchmarks
|
| 175 |
|
| 176 |
-
| dataset | Meridian-smaller | Granite-4.2-3B base | TwIL-LM3 | Llama-3.2-3B | LFM2-2.6B | LFM2.5-8B-A1B | Qwen3-8B | gpt-oss-120b ‡ |
|
| 177 |
-
|---|---:|---:|---:|---:|---:|---:|---:|---:|
|
| 178 |
-
| gsm8k | 0.9433 | 0.9533 | 0.8733 | 0.8300 | 0.8767 | 0.9133 | 0.9567 | **0.9767** |
|
| 179 |
-
| svamp | **0.9500** | 0.9200 | 0.8500 | 0.8200 | 0.9000 | 0.9133 | 0.9400 | 0.9400 |
|
| 180 |
-
| gsm_symbolic | 0.8267 | 0.8900 | 0.7567 | 0.8067 | **0.9767** | 0.9267 | 0.8133 | 0.8467 |
|
| 181 |
-
| arc_cot | 0.8600 | 0.8933 | 0.8467 | 0.7967 | 0.8667 | 0.9033 | 0.9633 | **0.9667** |
|
| 182 |
-
| logicbench | 0.7933 | 0.7733 | 0.7167 | 0.5733 | 0.6267 | 0.7200 |
|
| 183 |
-
| strategyqa | 0.5967 | 0.6267 | 0.6500 | 0.6533 | 0.6433 | 0.6667 | 0.7400 | **0.7867** |
|
| 184 |
-
| drop | 0.7367 | 0.7467 | 0.7467 | 0.6733 | 0.6900 | 0.6633 | **0.8833** | 0.8500 |
|
| 185 |
-
| csqa | 0.7667 | 0.7733 | 0.7367 | 0.7500 | 0.7433 | 0.7700 | **0.8633** | 0.8367 |
|
| 186 |
-
| musr | 0.6409 | 0.5922 | 0.4957 | 0.4932 | 0.4867 | 0.5703 | 0.6301 | **0.6852** |
|
| 187 |
-
| mmlu_redux | 0.7867 | 0.7733 | 0.6667 | 0.6000 | 0.7133 | 0.8367 | 0.8500 | **0.9467** |
|
| 188 |
-
| ifeval | 0.7500 | 0.7633 | 0.6433 | 0.7167 | 0.7300 | **0.8900** | 0.8400 | 0.7900 |
|
| 189 |
-
| rudas_ood | 0.0437 ¶¶ | 0.0012 | 0.0365 | **0.0733** | 0.0017 | 0.0061 | 0.0468 | 0.0000 ¶ |
|
| 190 |
-
| bbh_logic | 0.9540 | 0.9013 | 0.6633 | 0.5333 | 0.5713 | 0.7700 | 0.6367 | **0.9980** |
|
| 191 |
-
| math500 | 0.7467 | 0.6567 | 0.6900 | 0.4233 | 0.7133 | 0.7800 | 0.6100 | **0.8433** |
|
| 192 |
-
| **macro (10 CoT datasets)** | 0.7901 | 0.7942 | 0.7339 | 0.6997 | 0.7523 | 0.7884 | 0.8493 | **0.8689** |
|
| 193 |
-
| **macro (all 14)** | 0.7425 | 0.7332 | 0.6694 | 0.6245 | 0.6814 | 0.7378 | 0.7591 | **0.8086** |
|
| 194 |
-
| tok/s |
|
| 195 |
-
| mean gen length | ≈792 | ≈1282 | **482** | 510 | ≈796 | ≈1327 | ≈1931 | 801 |
|
| 196 |
-
| **ans/s** |
|
| 197 |
|
| 198 |
‡ MXFP4 weights, tensor-parallel 2 — quantized and multi-GPU, so not directly comparable to the
|
| 199 |
single-GPU BF16 rows. ¶ 74% of its `rudas_ood` generations hit the length cap, so that cell is a
|
|
@@ -202,11 +223,14 @@ truncation artefact rather than a measured score; excluding the row, its 13-data
|
|
| 202 |
cell is likewise a truncation artefact rather than a measurement of the model's ability.
|
| 203 |
|
| 204 |
Lengths marked ≈ are derived from stored generations rather than read from the run. For
|
| 205 |
-
Meridian-smaller
|
|
|
|
| 206 |
averaged over the 14 datasets (MuSR counted once); the same method reproduces TwIL-LM3's measured
|
| 207 |
482 to within 1%. The peer lengths marked ≈ use each model's characters-per-token ratio and are
|
| 208 |
-
carried over from the TwIL-LM3 card. `tok/s`
|
| 209 |
-
|
|
|
|
|
|
|
| 210 |
|
| 211 |
The honest summary of this table is that Meridian-smaller does not lead it. Larger models score
|
| 212 |
higher, and gpt-oss-120b leads seven of the fourteen dataset rows. Three things are worth
|
|
@@ -216,6 +240,14 @@ in-domain, which is the point of the WiSE-FT stage. Second, the 14-dataset macro
|
|
| 216 |
over the base, driven by BBH-logic, MATH-500 and MuSR. Third, it edges LFM2.5-8B-A1B on both
|
| 217 |
macros at less than half the parameters and leads the table outright on SVAMP (0.9500).
|
| 218 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 219 |
Track B here was run with the chat template's thinking mode **disabled** for Meridian-smaller and
|
| 220 |
its base (the prompt ends in an empty `<think></think>`), as it was for TwIL-LM3, whereas Track A
|
| 221 |
uses the default thinking mode. The Track B numbers therefore describe non-reasoning behaviour;
|
|
@@ -223,18 +255,41 @@ they are not a measure of what a thinking-mode generation would score. Some Trac
|
|
| 223 |
truncation-limited: MATH-500 hits the cap on 14.0% of rows, and SVAMP, GSM-Symbolic and
|
| 224 |
MuSR-team sit slightly above the 2% cap-hit threshold (3.0%, 3.0% and 2.8%).
|
| 225 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 226 |
### Checkpoint selection
|
| 227 |
|
| 228 |
MGPO checkpoints were compared on both tracks, and step 2580 was published because it has the
|
| 229 |
best (or tied-best) held-out score rather than the best in-domain gate:
|
| 230 |
|
| 231 |
-
| checkpoint | macro gate | macro_primary | B10 | B14 |
|
| 232 |
-
|---|---:|---:|---:|---:|
|
| 233 |
| WiSE-FT α = 0.15 (RL initialiser) | 0.531 | 0.583 | — | — |
|
| 234 |
-
| MGPO step 1200 | **0.569** | **0.598** | 0.7819 | 0.7362 |
|
| 235 |
-
| MGPO step 2000 | 0.557 | 0.581 | 0.7882 | 0.7425 |
|
| 236 |
-
| MGPO step 2200 | 0.567 | 0.583 | 0.7865 | 0.7406 |
|
| 237 |
-
| **MGPO step 2580 (published)** | 0.554 | 0.588 | **0.7901** | **0.7425** |
|
| 238 |
|
| 239 |
Track A gate here uses the same definition as the tables above (rule induction included).
|
| 240 |
Step 1200 leads the gate by 0.015 and `macro_primary` by 0.010, but step 2580 has the highest
|
|
@@ -340,8 +395,8 @@ hit the cap. That is far above the 2% threshold our protocol requires to mark a
|
|
| 340 |
than exact. The base is worse (49.2%), and both are pessimistic because a truncated response
|
| 341 |
scores zero regardless of reasoning quality — so the true Track A gap over the base is probably
|
| 342 |
narrower than +0.123, and part of the improvement is shorter generations rather than better
|
| 343 |
-
answers. For context, Qwen3-8B truncates 23.9% of rows, LFM2.5-8B-A1B 17.9%,
|
| 344 |
-
Llama-3.2-3B 10.0% under the same budget, TwIL-LM3 4.4%. Some Track B stages are also flagged
|
| 345 |
unrankable for the same reason (`rudas_ood` 93.7% cap-hit, `math500` 14.0%, plus marginal excess
|
| 346 |
on SVAMP, GSM-Symbolic and MuSR-team); the held-out core, retention, IFEval and log-likelihood
|
| 347 |
stages are rankable.
|
|
@@ -360,14 +415,16 @@ makes no claim about those. The weak absolute areas inside the specialisation ar
|
|
| 360 |
safety tuning beyond whatever the base model carries, and no instruction-following alignment
|
| 361 |
work — IFEval is 0.7500 against the base's 0.7633.
|
| 362 |
|
| 363 |
-
**Comparability.** For Track A, Meridian-smaller, its base, Qwen3-8B, LFM2-2.6B,
|
| 364 |
-
and Llama-3.2-3B were checked to share the same sampled-row manifest and dataset
|
| 365 |
-
decoding; the TwIL-LM3 and gpt-oss-120b values are carried over from the TwIL-LM3
|
| 366 |
-
describes the same harness. For Track B, the arms checked
|
| 367 |
-
|
| 368 |
-
Qwen3-8B and LFM2.5-8B-A1B; vLLM 0.11.2 for
|
| 369 |
-
|
| 370 |
-
|
|
|
|
|
|
|
| 371 |
|
| 372 |
## Evaluation protocol
|
| 373 |
|
|
@@ -378,6 +435,10 @@ differences of two to three points are within sampling noise.
|
|
| 378 |
`repetition_penalty = 1.0`, chat template applied with thinking disabled, vLLM backend.
|
| 379 |
- Both tracks use the same protocol for the model and its base, in a paired run over identical
|
| 380 |
sampled rows.
|
|
|
|
|
|
|
|
|
|
|
|
|
| 381 |
|
| 382 |
`repetition_penalty = 1.0` is load-bearing. A 1.1 penalty produced apparent 20-point swings on
|
| 383 |
Track B that were pure decoding artefact; the decoding kwargs are hashed into the protocol
|
|
|
|
| 33 |
macro is level with the base (0.7942 → 0.7901) and the 14-dataset macro improves slightly
|
| 34 |
(0.7332 → 0.7425). On the same harness and sampled rows it reaches the highest Track A macro
|
| 35 |
gate, strict-7 and six-lane average of any arm in the tables below for which each can be
|
| 36 |
+
computed, including Qwen3-8B, VibeThinker-3B and gpt-oss-120b (the 120B has no gate or strict-7 value).
|
| 37 |
|
| 38 |
+

|
| 39 |
|
| 40 |
## Highlights
|
| 41 |
|
|
|
|
| 55 |
Qwen3-8B (0.8493 / 0.7591) and gpt-oss-120b (0.8689 / 0.8086). It gains on BBH-logic
|
| 56 |
(0.9013 → 0.9540), MATH-500 (0.6567 → 0.7467) and MuSR (0.5922 → 0.6409), and gives back
|
| 57 |
GSM-Symbolic (0.8900 → 0.8267) and ARC (0.8933 → 0.8600).
|
| 58 |
+
* **Against VibeThinker-3B, a reasoning model of similar size.** Meridian-smaller leads it on all
|
| 59 |
+
six Track A lanes — macro gate 0.5539 against 0.4118, strict-7 0.2879 against 0.2021 — but not
|
| 60 |
+
on Track B, where VibeThinker-3B is ahead on the 10-dataset macro (0.8097 against 0.7901) and
|
| 61 |
+
Meridian-smaller is ahead on the 14-dataset macro (0.7425 against 0.7262). That 14-dataset lead
|
| 62 |
+
comes entirely from BBH-logic (0.9540 against 0.6107); without that row Meridian-smaller trails.
|
| 63 |
* **Structured formal output.** Tuned for the objects rather than the prose: FOL translation,
|
| 64 |
entailment labels, semantic parses, Lean statements and Lean proof critique.
|
| 65 |
* **Runs anywhere.** 3.66B parameters in bf16 (6.82 GiB), with a Q4\_K\_M GGUF at 2.09 GiB for
|
| 66 |
CPU or 4 GB of VRAM.
|
| 67 |
|
| 68 |
+
It is **not the most efficient**: it reasons at length. Track A generations average 1,902 tokens,
|
| 69 |
+
against 564 for TwIL-LM3, and 24.2% of them hit the length cap. Its raw decode rate is high
|
| 70 |
+
(21,169 tok/s †) but the long answers bring it to about 11 completed
|
| 71 |
+
answers per second †, against 28.1 for TwIL-LM3 and 4.5 for Qwen3-8B. It is also not a general
|
| 72 |
+
assistant — there is no safety or preference tuning here beyond what Granite 4.2 carries. See
|
| 73 |
[Limitations](#limitations-and-caveats).
|
| 74 |
|
| 75 |
## Model Details
|
|
|
|
| 99 |
|
| 100 |
### Track A — in-domain formal logic
|
| 101 |
|
| 102 |
+
Meridian-smaller, its base and VibeThinker-3B were run through the same harness, prompts, decoding
|
| 103 |
+
settings and sampled rows described under [Evaluation protocol](#evaluation-protocol), and the
|
| 104 |
+
other peer columns are the values already published for TwIL-LM3 on its card, produced by that
|
| 105 |
+
same harness (see [Comparability](#limitations-and-caveats)). Throughput rows come from a
|
| 106 |
+
dedicated decode-throughput protocol: `ans/s` is defined throughout as
|
| 107 |
+
`tok/s ÷ mean generation length`, so it measures completed answers rather than raw decode rate.
|
| 108 |
+
Cells marked † need the engine note below.
|
| 109 |
+
|
| 110 |
+
| lane / metric | Meridian-smaller | Granite-4.2-3B base | VibeThinker-3B | TwIL-LM3 | Llama-3.2-3B | LFM2-2.6B | LFM2.5-8B-A1B | Qwen3-8B | gpt-oss-120b ‡ |
|
| 111 |
+
|---|---:|---:|---:|---:|---:|---:|---:|---:|---:|
|
| 112 |
+
| lean_formalize token_f1 | 0.5092 | 0.2943 | 0.2087 | 0.5869 | 0.3690 | 0.1321 | 0.4655 | 0.4022 | **0.6306** |
|
| 113 |
+
| rule_induction derivation | 0.4195 | 0.2267 | 0.2038 | 0.3192 | 0.0825 | 0.0615 | 0.1936 | 0.3680 | **0.6518** |
|
| 114 |
+
| entailment_label accuracy | 0.6700 | 0.3000 | 0.5500 | 0.5750 | 0.3300 | 0.4700 | 0.5400 | 0.5800 | **0.7750** |
|
| 115 |
+
| mcq_answer accuracy | **0.4100** | 0.1200 | 0.1700 | 0.1100 | 0.0000 | 0.0150 | 0.0750 | 0.0000 | 0.0700 |
|
| 116 |
+
| semantic_parse token_f1 | 0.4295 | 0.3910 | 0.2422 | **0.4416** | 0.3102 | 0.3665 | 0.3778 | 0.4257 | 0.4331 |
|
| 117 |
+
| lean_critic accuracy | **0.7950** | **0.7950** | 0.6000 | 0.6600 | 0.5300 | 0.5900 | 0.5500 | **0.7950** | 0.5550 |
|
| 118 |
+
| lm_corpus perplexity ↓ | **2.3130** | 2.6334 | 16.9253 | 2.8972 | 2.8478 | 4.3815 | 4.9472 | 2.5440 | 912.23 § |
|
| 119 |
+
| math_corpus perplexity ↓ | **3.6983** | 4.4864 | 27.0318 | 3.8229 | 4.7531 | 6.7472 | 8.3323 | 4.0083 | 1045.63 § |
|
| 120 |
+
| average, 6 lanes | **0.5389** | 0.3545 | 0.3291 | 0.4488 | 0.2703 | 0.2725 | 0.3670 | 0.4285 | 0.5192 |
|
| 121 |
+
| **macro gate** | **0.5539** | 0.4313 | 0.4118 | 0.4218 | 0.2925 | 0.3473 | 0.3757 | 0.5336 | — |
|
| 122 |
+
| **strict-7** | **0.2879** | 0.1821 | 0.2021 | 0.1971 | 0.1229 | 0.1579 | 0.1714 | 0.2093 | — |
|
| 123 |
+
| macro_primary | **0.5875** | 0.4825 | 0.4637 | 0.4475 | 0.3450 | 0.4188 | 0.4213 | 0.5750 | — |
|
| 124 |
+
| tok/s | 21169 † | 21916 † | 28010 † | 15880 | 16160 | 25230 | 22480 | 9420 | 3374 |
|
| 125 |
+
| mean gen length | 1902 | 2951 | 2688 | **564** | 696 | 2296 | 1830 | 2094 | 1005 |
|
| 126 |
+
| **ans/s** | 11.1 † | 7.4 † | 10.4 † | **28.1** | 23.2 | 10.9 | 12.0 | 4.5 | 3.4 |
|
| 127 |
|
| 128 |
‡ **gpt-oss-120b** runs MXFP4 weights at tensor-parallel 2 — quantized and multi-GPU, so its
|
| 129 |
throughput rows are not directly comparable to the single-GPU BF16 arms. Its `procedural` lane
|
|
|
|
| 134 |
format and tokenizer make the corpus lanes score a different quantity. The number is reported
|
| 135 |
for completeness but is not a comparable measurement, and is excluded from the bolding.
|
| 136 |
|
| 137 |
+
† **Throughput for Meridian-smaller, its base and VibeThinker-3B** was measured with the same
|
| 138 |
+
dedicated protocol and prompt file as the peer columns (128 prompts × 512 generated tokens, EOS
|
| 139 |
+
ignored, greedy, `gpu_memory_utilization` 0.45, idle GPU), run on a single H200 with vLLM
|
| 140 |
+
0.19.1 in a later session, whereas the other columns are figures recorded earlier on vLLM 0.11.2. Engine effects
|
| 141 |
+
are architecture-dependent: in the same session TwIL-LM3 re-measured at 15,248 tok/s
|
| 142 |
+
against its published 15,880 (-4%), while VibeThinker-3B measured
|
| 143 |
+
28,010 against a published 18,116 (+55%). The †
|
| 144 |
+
cells are therefore comparable with each other, and only approximately with the older columns.
|
| 145 |
+
Meridian-smaller's two runs gave 20,454 and 21,884 tok/s (the first paid for cold
|
| 146 |
+
kernel caches) and the table shows their mean. `mean gen length` is measured directly under the
|
| 147 |
+
shared evaluation protocol and is comparable across every column.
|
| 148 |
|
| 149 |
**`average, 6 lanes`** is the plain mean of the six objective rows above it, each at whatever
|
| 150 |
scoring that row reports (Lean F1, rule derivation, entailment, MCQ strict, semantic F1, critic).
|
|
|
|
| 179 |
does not depend on loose-match credit — and Meridian-smaller leads on MCQ (strict 0.4100 against
|
| 180 |
0.0000), rule induction (0.4195 against 0.3680) and both perplexity lanes.
|
| 181 |
|
| 182 |
+
VibeThinker-3B — WeiboAI's 3B reasoning model, with 37.1% of its Track A generations truncated
|
| 183 |
+
— trails Meridian-smaller on every objective lane and every summary row: macro gate 0.4118 against
|
| 184 |
+
0.5539, strict-7 0.2021 against 0.2879, six-lane average 0.3291 against 0.5389. The gap is widest
|
| 185 |
+
on Lean formalisation (0.2087 against 0.5092) and narrowest on entailment (0.5500 against 0.6700).
|
| 186 |
+
Its corpus perplexities (16.93 and 27.03) are not comparable with the Granite-tokenizer models',
|
| 187 |
+
because perplexity is per token and its vocabulary is 151,936 against 100,352.
|
| 188 |
+
|
| 189 |
It does not lead every lane. gpt-oss-120b is clearly stronger on `rule_induction` (0.6518),
|
| 190 |
entailment (0.7750) and Lean formalisation (0.6306), and TwIL-LM3 remains ahead on Lean
|
| 191 |
formalisation (0.5869 against 0.5092) and semantic parsing (0.4416 against 0.4295). The two weak
|
|
|
|
| 194 |
|
| 195 |
### Track B — held-out benchmarks
|
| 196 |
|
| 197 |
+
| dataset | Meridian-smaller | Granite-4.2-3B base | VibeThinker-3B | TwIL-LM3 | Llama-3.2-3B | LFM2-2.6B | LFM2.5-8B-A1B | Qwen3-8B | gpt-oss-120b ‡ |
|
| 198 |
+
|---|---:|---:|---:|---:|---:|---:|---:|---:|---:|
|
| 199 |
+
| gsm8k | 0.9433 | 0.9533 | 0.9600 | 0.8733 | 0.8300 | 0.8767 | 0.9133 | 0.9567 | **0.9767** |
|
| 200 |
+
| svamp | **0.9500** | 0.9200 | 0.9367 | 0.8500 | 0.8200 | 0.9000 | 0.9133 | 0.9400 | 0.9400 |
|
| 201 |
+
| gsm_symbolic | 0.8267 | 0.8900 | 0.8167 | 0.7567 | 0.8067 | **0.9767** | 0.9267 | 0.8133 | 0.8467 |
|
| 202 |
+
| arc_cot | 0.8600 | 0.8933 | 0.9033 | 0.8467 | 0.7967 | 0.8667 | 0.9033 | 0.9633 | **0.9667** |
|
| 203 |
+
| logicbench | 0.7933 | 0.7733 | **0.8600** | 0.7167 | 0.5733 | 0.6267 | 0.7200 | 0.8567 | 0.8533 |
|
| 204 |
+
| strategyqa | 0.5967 | 0.6267 | 0.6467 | 0.6500 | 0.6533 | 0.6433 | 0.6667 | 0.7400 | **0.7867** |
|
| 205 |
+
| drop | 0.7367 | 0.7467 | 0.8467 | 0.7467 | 0.6733 | 0.6900 | 0.6633 | **0.8833** | 0.8500 |
|
| 206 |
+
| csqa | 0.7667 | 0.7733 | 0.7367 | 0.7367 | 0.7500 | 0.7433 | 0.7700 | **0.8633** | 0.8367 |
|
| 207 |
+
| musr | 0.6409 | 0.5922 | 0.5799 | 0.4957 | 0.4932 | 0.4867 | 0.5703 | 0.6301 | **0.6852** |
|
| 208 |
+
| mmlu_redux | 0.7867 | 0.7733 | 0.8100 | 0.6667 | 0.6000 | 0.7133 | 0.8367 | 0.8500 | **0.9467** |
|
| 209 |
+
| ifeval | 0.7500 | 0.7633 | 0.6633 | 0.6433 | 0.7167 | 0.7300 | **0.8900** | 0.8400 | 0.7900 |
|
| 210 |
+
| rudas_ood | 0.0437 ¶¶ | 0.0012 | 0.0056 | 0.0365 | **0.0733** | 0.0017 | 0.0061 | 0.0468 | 0.0000 ¶ |
|
| 211 |
+
| bbh_logic | 0.9540 | 0.9013 | 0.6107 | 0.6633 | 0.5333 | 0.5713 | 0.7700 | 0.6367 | **0.9980** |
|
| 212 |
+
| math500 | 0.7467 | 0.6567 | 0.7900 | 0.6900 | 0.4233 | 0.7133 | 0.7800 | 0.6100 | **0.8433** |
|
| 213 |
+
| **macro (10 CoT datasets)** | 0.7901 | 0.7942 | 0.8097 | 0.7339 | 0.6997 | 0.7523 | 0.7884 | 0.8493 | **0.8689** |
|
| 214 |
+
| **macro (all 14)** | 0.7425 | 0.7332 | 0.7262 | 0.6694 | 0.6245 | 0.6814 | 0.7378 | 0.7591 | **0.8086** |
|
| 215 |
+
| tok/s | 21169 † | 21916 † | 28010 † | 15880 | 16160 | 25230 | 22480 | 9420 | 3374 |
|
| 216 |
+
| mean gen length | ≈792 | ≈1282 | ≈1789 | **482** | 510 | ≈796 | ≈1327 | ≈1931 | 801 |
|
| 217 |
+
| **ans/s** | 26.7 † | 17.1 † | ≈15.7 † | **32.9** | 31.7 | ≈31.7 | ≈16.9 | 4.9 | 4.2 |
|
| 218 |
|
| 219 |
‡ MXFP4 weights, tensor-parallel 2 — quantized and multi-GPU, so not directly comparable to the
|
| 220 |
single-GPU BF16 rows. ¶ 74% of its `rudas_ood` generations hit the length cap, so that cell is a
|
|
|
|
| 223 |
cell is likewise a truncation artefact rather than a measurement of the model's ability.
|
| 224 |
|
| 225 |
Lengths marked ≈ are derived from stored generations rather than read from the run. For
|
| 226 |
+
Meridian-smaller, its base and VibeThinker-3B they were re-tokenized directly with each model's
|
| 227 |
+
own tokenizer and
|
| 228 |
averaged over the 14 datasets (MuSR counted once); the same method reproduces TwIL-LM3's measured
|
| 229 |
482 to within 1%. The peer lengths marked ≈ use each model's characters-per-token ratio and are
|
| 230 |
+
carried over from the TwIL-LM3 card. † `tok/s` is the same throughput figure as in Track A (see
|
| 231 |
+
the engine note under that table) and `ans/s` divides it by the mean generation length shown. The
|
| 232 |
+
VibeThinker-3B Track B rows come from the same external-baseline run and vLLM 0.11.2 engine as
|
| 233 |
+
the other external peers.
|
| 234 |
|
| 235 |
The honest summary of this table is that Meridian-smaller does not lead it. Larger models score
|
| 236 |
higher, and gpt-oss-120b leads seven of the fourteen dataset rows. Three things are worth
|
|
|
|
| 240 |
over the base, driven by BBH-logic, MATH-500 and MuSR. Third, it edges LFM2.5-8B-A1B on both
|
| 241 |
macros at less than half the parameters and leads the table outright on SVAMP (0.9500).
|
| 242 |
|
| 243 |
+
VibeThinker-3B is the stronger held-out model on the 10-dataset macro (0.8097 against 0.7901). It
|
| 244 |
+
is ahead of Meridian-smaller on seven datasets — GSM8K, ARC, LogicBench, StrategyQA, DROP,
|
| 245 |
+
MMLU-Redux and MATH-500 — and behind on the other seven: SVAMP, GSM-Symbolic, CSQA, MuSR, IFEval,
|
| 246 |
+
BBH-logic and `rudas_ood`. Meridian-smaller's 0.0163 lead on the 14-dataset macro comes entirely
|
| 247 |
+
from BBH-logic (0.9540 against 0.6107): on the other thirteen datasets it averages 0.7263 against
|
| 248 |
+
VibeThinker-3B's 0.7350. VibeThinker-3B also writes much longer answers on Track B (about 1,789
|
| 249 |
+
tokens against 792).
|
| 250 |
+
|
| 251 |
Track B here was run with the chat template's thinking mode **disabled** for Meridian-smaller and
|
| 252 |
its base (the prompt ends in an empty `<think></think>`), as it was for TwIL-LM3, whereas Track A
|
| 253 |
uses the default thinking mode. The Track B numbers therefore describe non-reasoning behaviour;
|
|
|
|
| 255 |
truncation-limited: MATH-500 hits the cap on 14.0% of rows, and SVAMP, GSM-Symbolic and
|
| 256 |
MuSR-team sit slightly above the 2% cap-hit threshold (3.0%, 3.0% and 2.8%).
|
| 257 |
|
| 258 |
+
### Against the tuned VibeThinker-3B
|
| 259 |
+
|
| 260 |
+
The tables above use the public VibeThinker-3B checkpoint. The same post-training pipeline was also
|
| 261 |
+
applied to it, and the best tuned configuration (WiSE-FT, λ = 0.50) is the closest same-scale
|
| 262 |
+
comparison to Meridian-smaller. These values come from the family comparison tables rather than
|
| 263 |
+
from a per-lane raw report, so they are shown as a summary only:
|
| 264 |
+
|
| 265 |
+
| model | macro gate | macro_primary | B10 | B14 | Track A truncation |
|
| 266 |
+
|---|---:|---:|---:|---:|---:|
|
| 267 |
+
| Meridian-smaller | **0.554** | **0.588** | 0.790 | **0.743** | 24.2% |
|
| 268 |
+
| VibeThinker-3B, WiSE-FT λ = 0.50 | 0.541 | **0.588** | **0.802** | 0.728 ◊ | 14.3% |
|
| 269 |
+
|
| 270 |
+
◊ There is no B14 row for the λ = 0.50 configuration; the figure is the best tuned VibeThinker-3B
|
| 271 |
+
B14 in the family table (SLERP, d = 0.5, t = 0.5).
|
| 272 |
+
|
| 273 |
+
The two are effectively tied on Track A (macro gate 0.554 against 0.541, `macro_primary` equal at
|
| 274 |
+
0.588, both within sampling noise at n = 200), and the tuned VibeThinker-3B is ahead on the
|
| 275 |
+
10-dataset macro (0.802 against 0.790) with a lower truncation rate. Meridian-smaller's edge is the
|
| 276 |
+
14-dataset macro (0.743 against 0.728), a gap that cannot be broken down per dataset from the
|
| 277 |
+
summary values. Read gaps to the
|
| 278 |
+
*untuned* VibeThinker-3B within one source: the family table records that checkpoint at a gate of
|
| 279 |
+
0.374, from a separate run of the same weights than the 0.4118 in the lane tables above.
|
| 280 |
+
|
| 281 |
### Checkpoint selection
|
| 282 |
|
| 283 |
MGPO checkpoints were compared on both tracks, and step 2580 was published because it has the
|
| 284 |
best (or tied-best) held-out score rather than the best in-domain gate:
|
| 285 |
|
| 286 |
+
| checkpoint | macro gate | macro_primary | B10 | B14 |
|
| 287 |
+
|---|---:|---:|---:|---:|
|
| 288 |
| WiSE-FT α = 0.15 (RL initialiser) | 0.531 | 0.583 | — | — |
|
| 289 |
+
| MGPO step 1200 | **0.569** | **0.598** | 0.7819 | 0.7362 |
|
| 290 |
+
| MGPO step 2000 | 0.557 | 0.581 | 0.7882 | 0.7425 |
|
| 291 |
+
| MGPO step 2200 | 0.567 | 0.583 | 0.7865 | 0.7406 |
|
| 292 |
+
| **MGPO step 2580 (published)** | 0.554 | 0.588 | **0.7901** | **0.7425** |
|
| 293 |
|
| 294 |
Track A gate here uses the same definition as the tables above (rule induction included).
|
| 295 |
Step 1200 leads the gate by 0.015 and `macro_primary` by 0.010, but step 2580 has the highest
|
|
|
|
| 395 |
than exact. The base is worse (49.2%), and both are pessimistic because a truncated response
|
| 396 |
scores zero regardless of reasoning quality — so the true Track A gap over the base is probably
|
| 397 |
narrower than +0.123, and part of the improvement is shorter generations rather than better
|
| 398 |
+
answers. For context, Qwen3-8B truncates 23.9% of rows, VibeThinker-3B 37.1%, LFM2.5-8B-A1B 17.9%,
|
| 399 |
+
LFM2-2.6B 41.3% and Llama-3.2-3B 10.0% under the same budget, TwIL-LM3 4.4%. Some Track B stages are also flagged
|
| 400 |
unrankable for the same reason (`rudas_ood` 93.7% cap-hit, `math500` 14.0%, plus marginal excess
|
| 401 |
on SVAMP, GSM-Symbolic and MuSR-team); the held-out core, retention, IFEval and log-likelihood
|
| 402 |
stages are rankable.
|
|
|
|
| 415 |
safety tuning beyond whatever the base model carries, and no instruction-following alignment
|
| 416 |
work — IFEval is 0.7500 against the base's 0.7633.
|
| 417 |
|
| 418 |
+
**Comparability.** For Track A, Meridian-smaller, its base, VibeThinker-3B, Qwen3-8B, LFM2-2.6B,
|
| 419 |
+
LFM2.5-8B-A1B and Llama-3.2-3B were checked to share the same sampled-row manifest and dataset
|
| 420 |
+
hash, seed and decoding; the TwIL-LM3 and gpt-oss-120b values are carried over from the TwIL-LM3
|
| 421 |
+
card, which describes the same harness. For Track B, the arms checked (including VibeThinker-3B,
|
| 422 |
+
on all 18 tasks) share the same sampled rows and decoding, but the serving engine differs between
|
| 423 |
+
arms (vLLM 0.19.1 for Meridian-smaller, its base, Qwen3-8B and LFM2.5-8B-A1B; vLLM 0.11.2 for
|
| 424 |
+
TwIL-LM3, Llama-3.2-3B and VibeThinker-3B), and the engine version is part of the protocol hash.
|
| 425 |
+
Throughput has its own, separate engine caveat (see the † note under the Track A table). With
|
| 426 |
+
n = 200 per lane on Track A and n = 300 per dataset on Track B, differences of two to three points
|
| 427 |
+
are within sampling noise.
|
| 428 |
|
| 429 |
## Evaluation protocol
|
| 430 |
|
|
|
|
| 435 |
`repetition_penalty = 1.0`, chat template applied with thinking disabled, vLLM backend.
|
| 436 |
- Both tracks use the same protocol for the model and its base, in a paired run over identical
|
| 437 |
sampled rows.
|
| 438 |
+
- Throughput: 128 prompts drawn from a fixed Track A prompt file, 512 generated tokens each with
|
| 439 |
+
EOS ignored, greedy, vLLM `gpu_memory_utilization` 0.45, `max_model_len` 4096, on an otherwise
|
| 440 |
+
idle GPU (a single H200 for the Meridian-smaller, base and VibeThinker-3B runs); the reported rate is generated tokens over decode time, excluding engine start-up and
|
| 441 |
+
compilation.
|
| 442 |
|
| 443 |
`repetition_penalty = 1.0` is load-bearing. A 1.1 penalty produced apparent 20-point swings on
|
| 444 |
Track B that were pure decoding artefact; the decoding kwargs are hashed into the protocol
|
benchmarks.png
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|