---
license: other
license_name: qwen-research
base_model: Qwen/Qwen-Image-2.1
library_name: diffusers
pipeline_tag: text-to-image
tags:
- qwen
- image-generation
- image-editing
- rgba
- lora
- distilled
- few-step
---
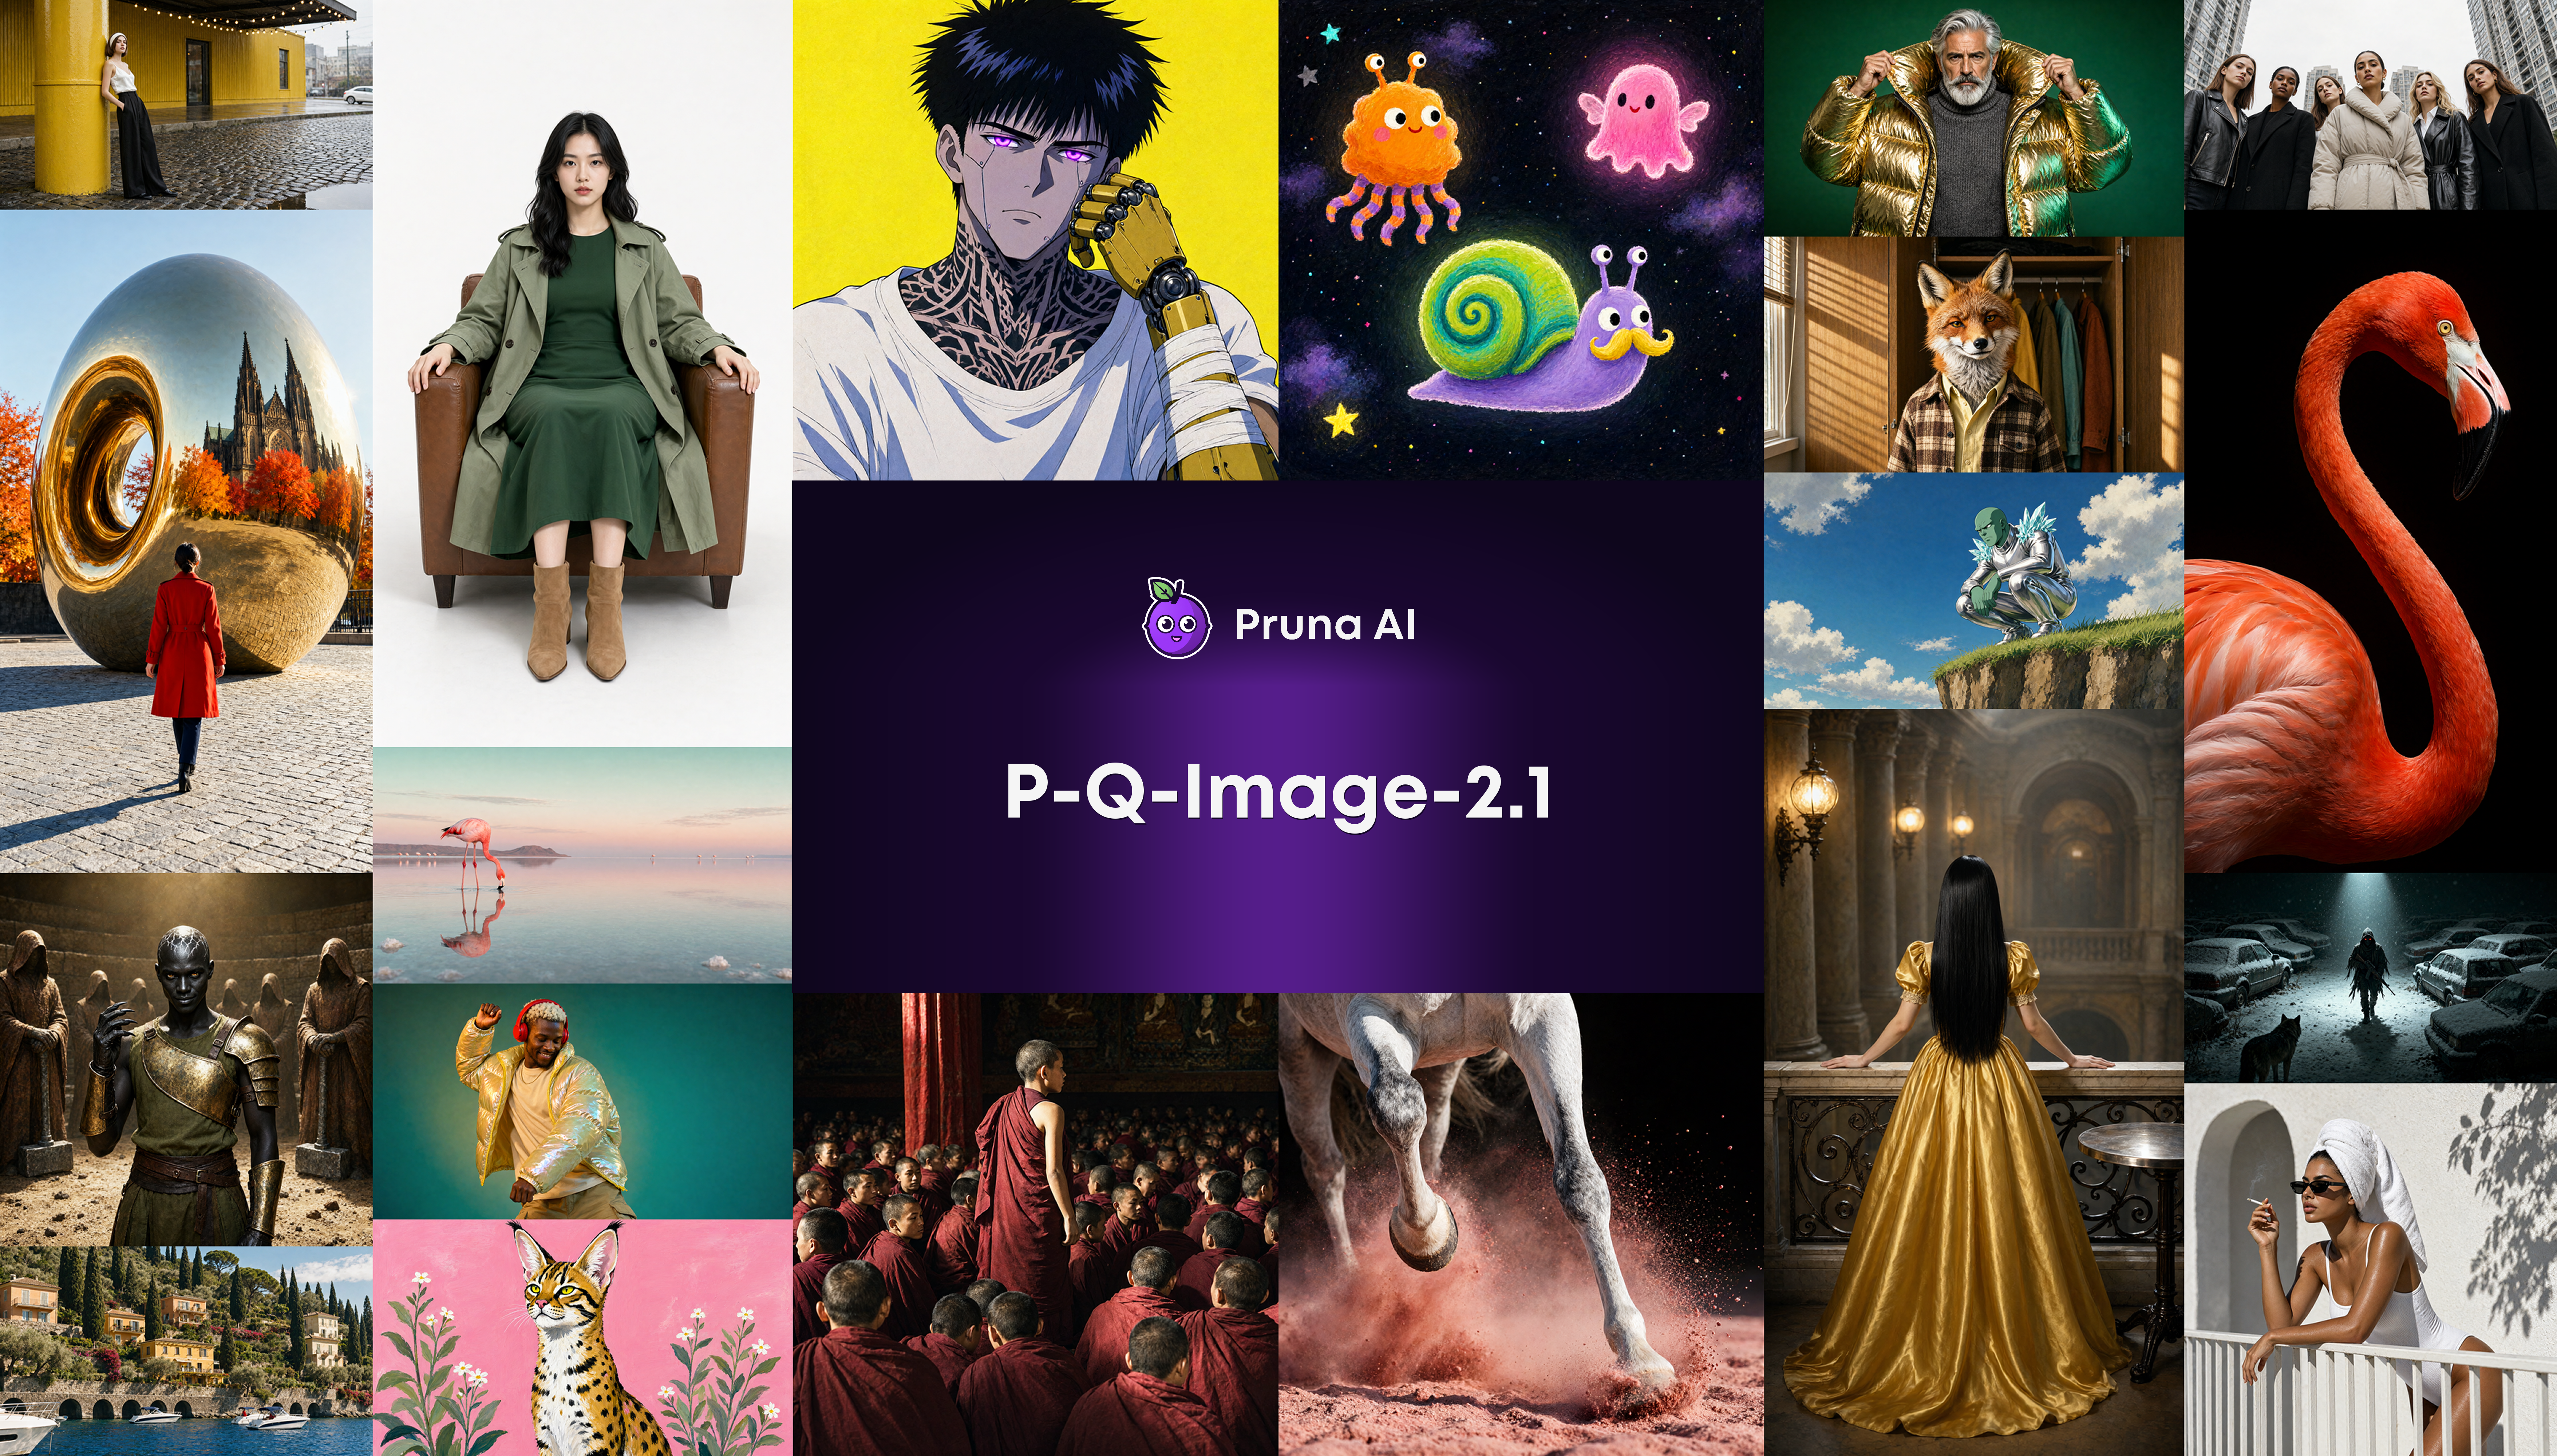

⚡ P-Q-Image-2.1
Few-step LoRA adapters for Qwen-Image-2.1
6 steps (v0.2), 5 or 8 steps (v0.1)
·
Up to 6.3x faster
·
No CFG
·
Text-to-image and image editing
**P-Q-Image-2.1** is a set of LoRA adapters that let
[`Qwen/Qwen-Image-2.1`](https://huggingface.co/Qwen/Qwen-Image-2.1) generate
and edit images in only 6 steps (v0.2), or 5 or 8 steps (v0.1). The adapters load on top of the base
model, so the pipeline, text encoder, and VAE stay unchanged.
> **v0.2: two new 6-step adapters.**
>
> - An advanced distillation for more faithful generation and editing.
> - The first distillation removing need for prompt upsampling into the LoRA, thus significantly reducing end-to-end generation.
> The v0.1 adapters remain available.
## 6-step variants
Pick **6-steps** for faithful base-model behavior, or **6-steps-upsampled** for
improved visual quality from a short prompt, without a separate prompt-upsampling call.
| Variant | File | Steps | Trade-off |
|---|---|:---:|---|
| `6-steps` | `p_q_image_2.1_6_steps_v0.2.safetensors` | 6 | **Advanced distillation.** Recommended for preserving inputs when editing. |
| `6-steps-upsampled` | `p_q_image_2.1_6_steps_upsampled_v0.2.safetensors` | 6 | **Improved visual quality, shorter end-to-end generation.** The first distillation that removes the need for a separate prompt-upsampling step. |
**6-steps** is an advanced 6-step distillation of the base model. It is intended
as a drop-in replacement for the base model in existing generation and editing
workflows, using the adapter's step count and sigma schedule. It improves on the
v0.1 adapters in almost all categories and is particularly good at editing tasks
where preserving the input matters.
**6-steps-upsampled** distills the prompt upsampler recommended for
Qwen-Image-2.1 into a 6-step LoRA. It improves visual quality without a separate
prompt-upsampling call, which significantly reduces end-to-end generation time.
It may not reproduce exactly what the actual prompt upsampler would do, and we
will continue improving it.
See the 5-step vs 8-step adapters (v0.1)
### v0.1
Both adapters are v0.1. Pick one based on whether you need **quality** or **speed**.
| Variant | File | Steps | Trade-off |
|---|---|:---:|---|
| `8-steps` | `p_q_image_2.1_8_steps_v0.1.safetensors` | 8 | **Higher quality.** Recommended as the default. |
| `5-steps` | `p_q_image_2.1_5_steps_v0.1.safetensors` | 5 | **Higher speed**, with noticeably lower visual quality. |
Each adapter is trained for its own sigma schedule. Load only one at a time.
For the v0.2 adapters, do not reuse the v0.1 schedules.
## Prompts, editing, and resolution
For **6-steps**, use the same prompts and reference images you would use with the
base model. For **6-steps-upsampled**, start with your original prompt; the adapter
is intended to capture the benefit of prompt upsampling during generation.
Detailed prompts still let you specify the subject, setting, lighting, and style.
The adapters were trained at **1K resolution only**, with a mix of simple and
upsampled prompts, text-to-image generation, and single- and multi-image editing
with **up to 3 reference images**. Prompt upsampling is optional; detailed prompts
usually give better results.
Start at **1024 × 1024** and use at most **3 reference images** for editing.
Higher resolutions (including 2K) and more reference images may work, but are
outside the training coverage, and quality may vary. The 2K timings below show
inference speed, not a guarantee of quality at that resolution.
## Quickstart
Runs text-to-image and image editing with the same pipeline. Needs a **CUDA GPU**.
```bash
pip install 'torch>=2.4.0' 'transformers>=5.17' accelerate peft pillow
pip install git+https://github.com/huggingface/diffusers@6256aa7666cedd47443adc8f82da9a10e110b09c
```
Use this setup for either v0.2 adapter.
```python
import torch
from PIL import Image
from diffusers import FlowMatchEulerDiscreteScheduler, QwenImage21Pipeline
# Both v0.2 adapters use this unshifted six-step schedule.
# The scheduler applies the resolution-dependent shift and appends sigma 0.
STEPS = 6
VARIANT = "6-steps" # "6-steps" or "6-steps-upsampled"
WEIGHT_NAME = {
"6-steps": "p_q_image_2.1_6_steps_v0.2.safetensors",
"6-steps-upsampled": "p_q_image_2.1_6_steps_upsampled_v0.2.safetensors",
}[VARIANT]
SIGMAS = [1.0, 0.925, 0.85, 0.625, 0.375, 0.125]
pipe = QwenImage21Pipeline.from_pretrained(
"Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")
pipe.load_lora_weights(
"PrunaAI/P-Q-Image-2.1",
weight_name=WEIGHT_NAME,
)
# Shift the raw sigmas using the base model's resolution-dependent settings.
pipe.scheduler = FlowMatchEulerDiscreteScheduler.from_config(
pipe.scheduler.config,
use_dynamic_shifting=True,
shift_terminal=None,
)
```
Both variants load on **`Qwen/Qwen-Image-2.1`** using **`QwenImage21Pipeline`**.
Choose one LoRA with `VARIANT`; the `6-steps-upsampled` variant runs directly on your
original prompt without a separate prompt-enhancer model. For a local export,
replace `"PrunaAI/P-Q-Image-2.1"` with the folder containing the chosen
safetensors file and keep `weight_name=WEIGHT_NAME`.
Both files have **rank 64** across **232 linear targets**, including `proj_out`.
Training used alpha 128; the exported B matrices include the `128 / 64 = 2`
scale. Load at **LoRA strength 1.0** with the standard pipeline loader.
Check more info for the 5–8 step setup (v0.1)
### v0.1
```python
import torch
from PIL import Image
from diffusers import FlowMatchEulerDiscreteScheduler, QwenImage21Pipeline
STEPS = 8 # 8 for higher quality, 5 for higher speed
# The terminal sigma 0 is appended by the scheduler.
SIGMAS = {
5: [1.0, 0.94, 6 / 7, 2 / 3, 0.4],
8: [1.0, 14 / 15, 6 / 7, 10 / 13, 2 / 3, 6 / 11, 0.4, 2 / 9],
}[STEPS]
pipe = QwenImage21Pipeline.from_pretrained(
"Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")
pipe.load_lora_weights(
"PrunaAI/P-Q-Image-2.1",
weight_name=f"p_q_image_2.1_{STEPS}_steps_v0.1.safetensors",
)
# Use the sigmas exactly as given: no extra shifting.
pipe.scheduler = FlowMatchEulerDiscreteScheduler.from_config(
pipe.scheduler.config,
use_dynamic_shifting=False,
shift=1.0,
shift_terminal=None,
)
```
## Benchmarking
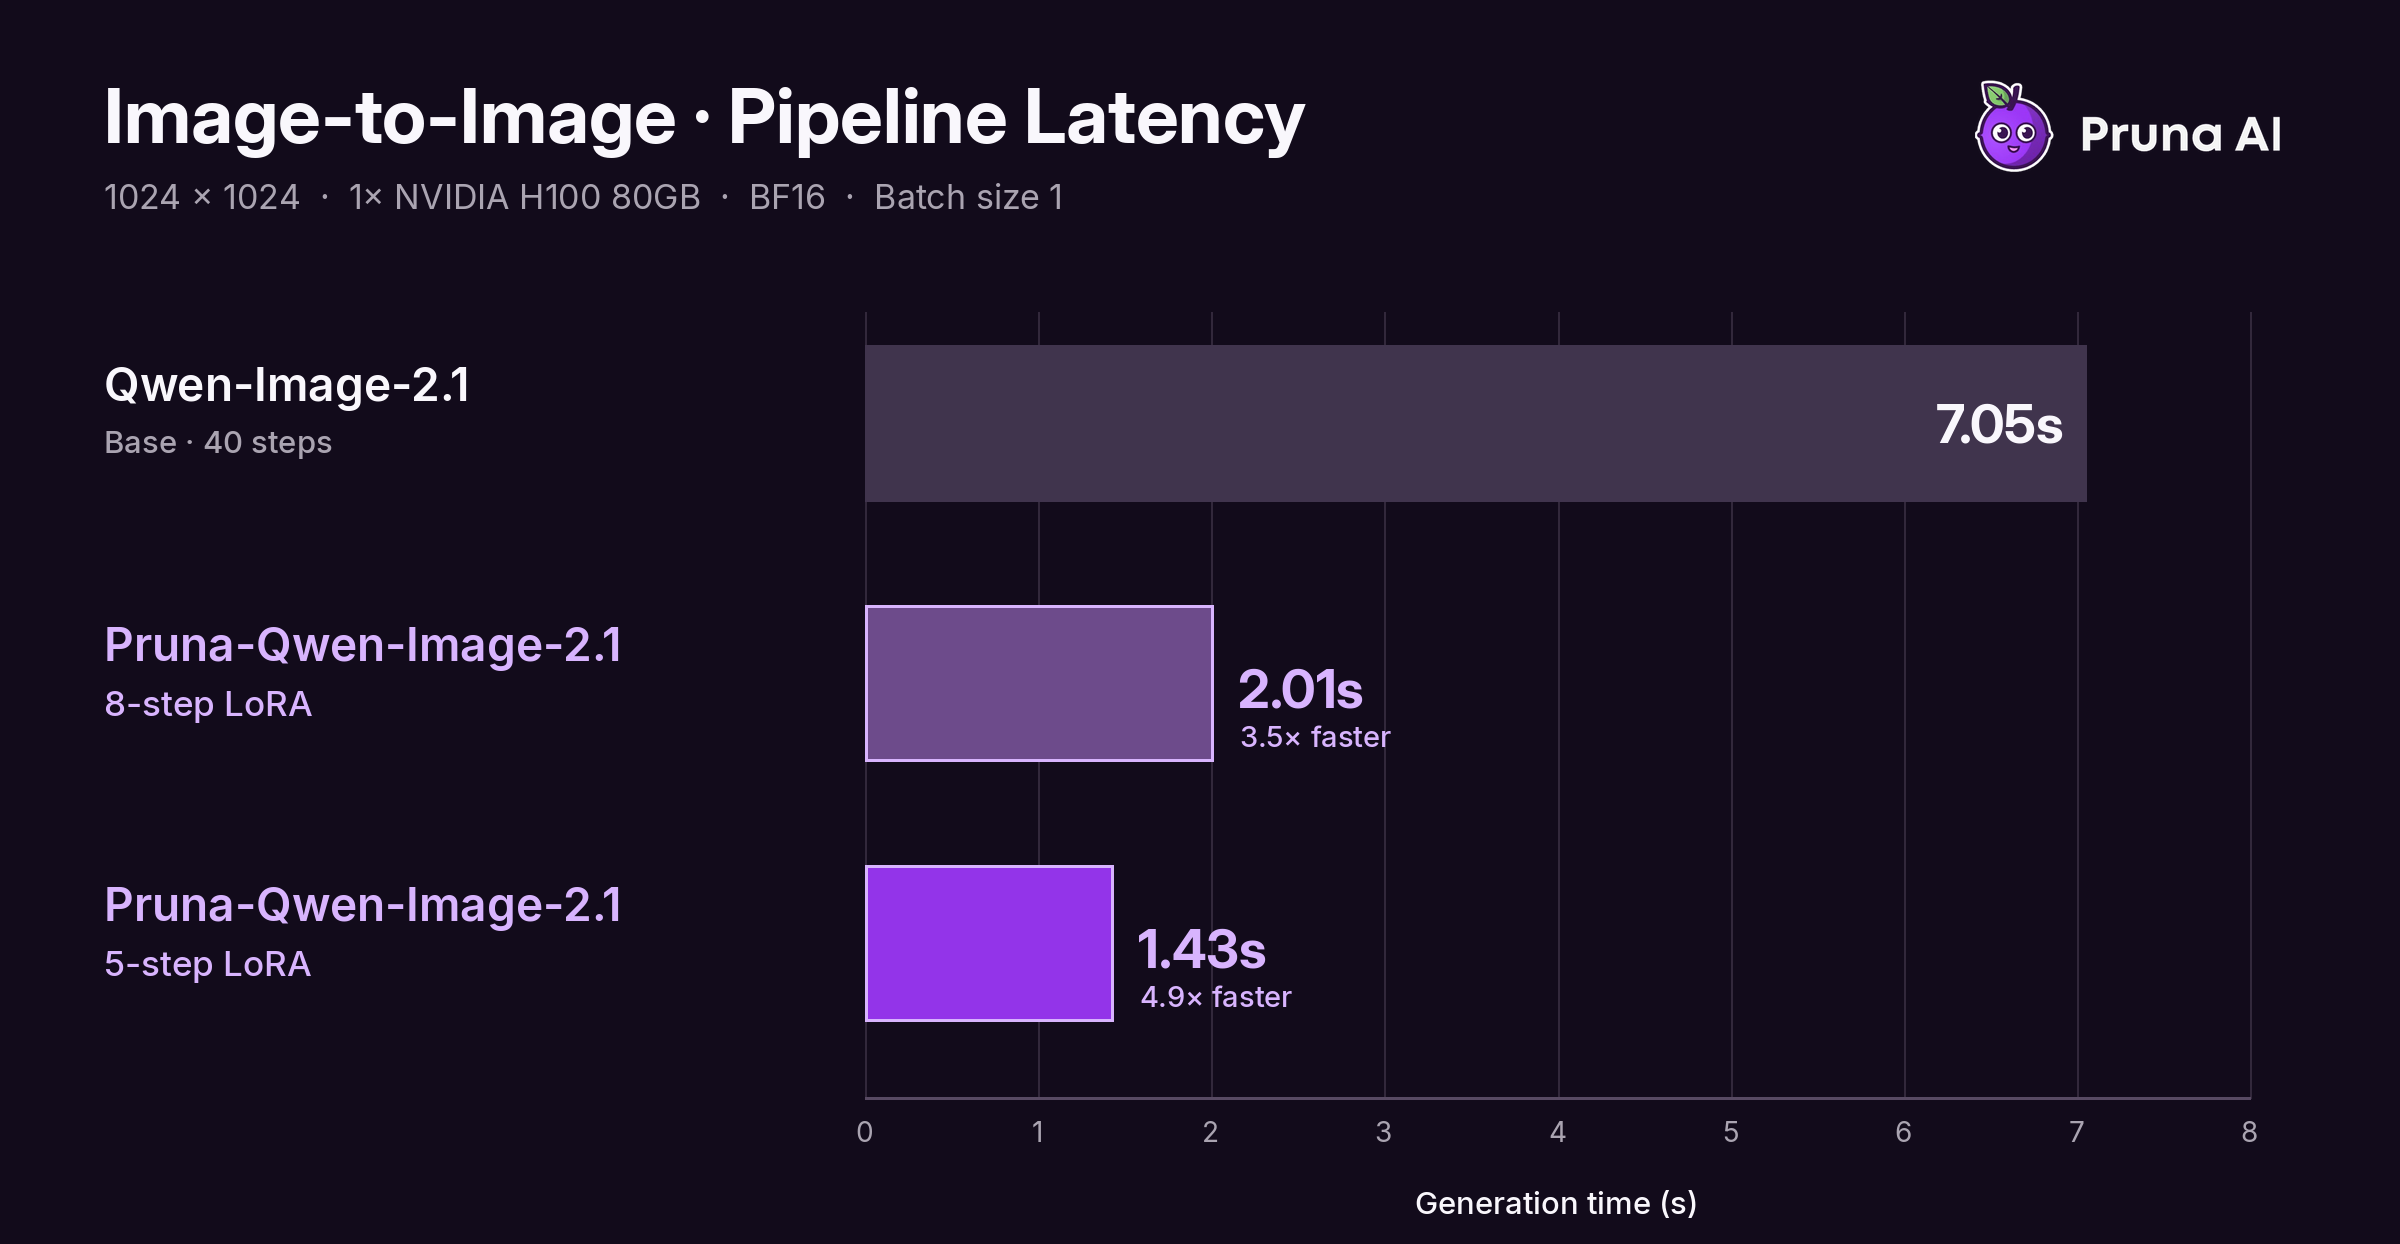
|

|
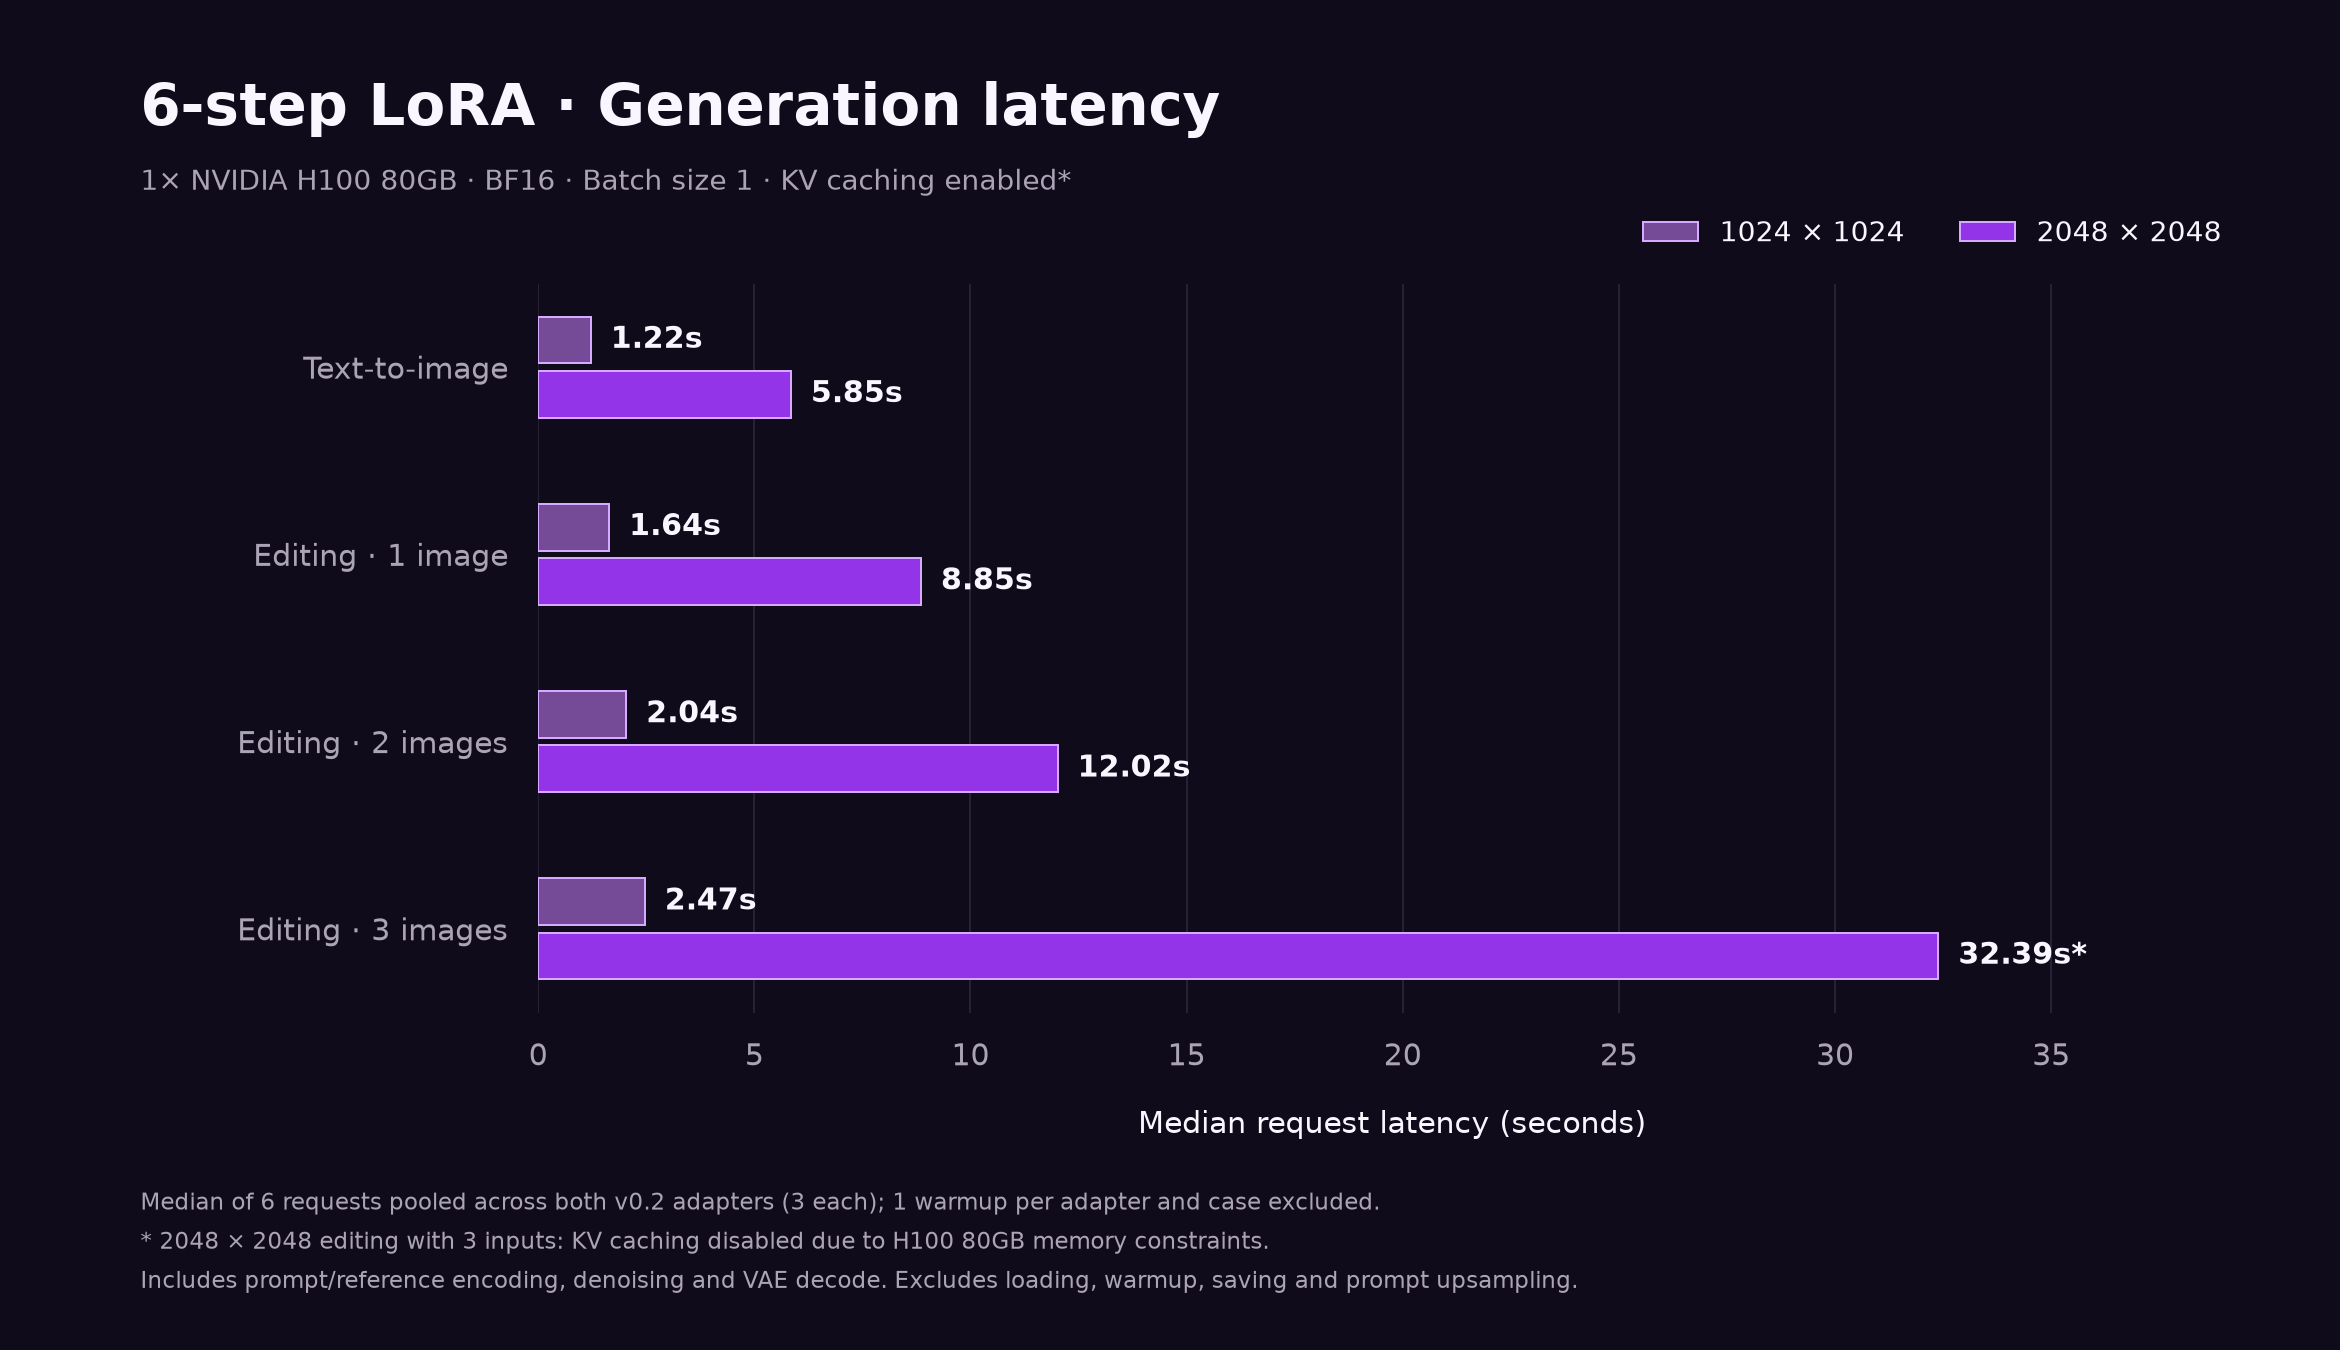
One NVIDIA H100 80GB, BF16, batch size 1. v0.2 generation timings
report the median of six measured requests pooled across both adapters (three
per adapter), excluding one warmup per adapter and case.
Generation includes prompt encoding, reference-image processing, denoising, and
VAE decode. It excludes loading, warmup, fixture prep, saving, and network.
No CFG, compilation, or CPU offload. **Diffusion KV caching is enabled**, except
for the case marked with an asterisk below.
\* **2048 × 2048 editing with 3 input images:** KV caching was disabled due to
memory constraints on the H100 80GB. The 2048 multi-image cases use expandable
CUDA memory segments (`PYTORCH_ALLOC_CONF=expandable_segments:True`).
Prompt upsampling is timed separately with
[`Qwen-Image-2.1-PE-T2I`](https://huggingface.co/Qwen/Qwen-Image-2.1-PE-T2I)
and [`Qwen-Image-2.1-PE-I2I`](https://huggingface.co/Qwen/Qwen-Image-2.1-PE-I2I).
It covers request prep through parsed text, not image generation. vLLM runs
eager, without prefix or image-processor caching, and with a fresh image ID so
vision encoding is always counted. Autoregressive KV cache stays on.
Text-to-image uses a fixed neon-sign prompt. Editing uses a fixed
prompt and 1–3 reference images, square-cropped and resized. These cases are
not matched to the v0.1 charts, and adding the two medians is not an
end-to-end time.
Generation: PyTorch 2.11.0, CUDA 12.8, Transformers 5.20.1, PEFT 0.21.2,
Diffusers `6256aa7666cedd47443adc8f82da9a10e110b09c`. Upsampling: vLLM 0.19.1,
PyTorch 2.10.0, Transformers 5.19.0. The v0.1 charts were not rerun here.
Both enhancers use thinking with
`temperature=1.0`, `top_p=0.95`, `top_k=20`, `min_p=0.0`. Text-to-image:
`presence_penalty=1.5`, 16,256-token cap. Editing: `presence_penalty=0.0`,
24,000-token cap. Reported only if all three rewrites complete and parse.
Check more info for the 5–8 step benchmarks (v0.1)
### v0.1
Text-to-image with the official Qwen model-card example prompt, BF16, batch size 1,
on one NVIDIA H100 80GB. Median of 3 requests after one warmup per configuration.
Includes prompt encoding, denoising, and decoding; excludes PNG saving, model
loading, and warmup. Base: 40 steps with KV cache on; P-Q-Image-2.1: 5 or 8 steps with
KV cache off, as configured for this benchmark. The examples below enable KV caching for
P-Q-Image-2.1; the chart has not been remeasured with that setting. LoRAs were unmerged;
no CFG, compilation, or CPU offload. These timings do not imply equal image quality.
## For Text-to-Image
Longer, more descriptive prompts give better results.
```python
image = pipe(
prompt=(
'A glowing neon shop sign that reads "QWEN IMAGE 2.1", mounted on a brick wall '
"in a narrow city alley at night. Heavy rain, wet pavement reflecting pink and "
"blue light, shallow depth of field, cinematic photograph."
),
width=1024,
height=1024,
generator=torch.Generator("cuda").manual_seed(42),
num_inference_steps=STEPS,
sigmas=SIGMAS,
true_cfg_scale=1.0,
use_kv_cache=True,
).images[0]
```
### For Image Editing
```python
image = pipe(
prompt="Change the background to a sunset beach",
image=Image.open("input.png").convert("RGB"),
generator=torch.Generator("cuda").manual_seed(42),
num_inference_steps=STEPS,
sigmas=SIGMAS,
true_cfg_scale=1.0,
use_kv_cache=True,
).images[0]
```
### Recommended settings
- Use the unshifted six-step sigmas `[1.0, 0.925, 0.85, 0.625, 0.375, 0.125]` with dynamic shifting enabled
and `shift_terminal=None`, as shown in the v0.2 setup.
- The scheduler appends terminal zero.
- Keep `true_cfg_scale=1.0` and LoRA strength 1.0.
Recommended 5–8 step settings (v0.1)
### v0.1 settings
- **Use the sigma schedule that matches your adapter**, and keep the scheduler
at `shift=1.0` with dynamic shifting off so the sigmas are not shifted twice.
- 8-step: `1 → 14/15 → 6/7 → 10/13 → 2/3 → 6/11 → 0.4 → 2/9 → 0`
(shift 2, computed as `σ = 2t / (1 + t)` on evenly spaced `t`)
- 5-step: `1 → 0.94 → 6/7 → 2/3 → 0.4 → 0`
- **No CFG.** Keep `true_cfg_scale=1.0` and do not pass a negative prompt.
- **Keep the LoRA strength at 1.0.**
- **Write detailed prompts for text-to-image.** Longer prompts that describe
the subject, setting, lighting, and style work noticeably better than short
ones.
## Limitations
- The `6-steps-upsampled` adapter can improve visual quality without a separate
prompt-upsampling call, but may not exactly reproduce the output of the actual
prompt upsampler.
- `6-steps` is intended to preserve the base model's behavior in fewer steps;
distillation does not guarantee identical outputs.
- Use the step count and sigma schedule that match your v0.2 adapter. Other step
counts, schedules, or CFG values are not supported.
Known limits of the 5–8 step adapters (v0.1)
### v0.1
- This is a first version. Quality is below that of the base model.
- The 5-step adapter is faster than the 8-step one, but its images are
visibly worse.
- Short or vague text-to-image prompts give weaker results.
- The adapters are only intended for the settings above. Other step counts,
schedules, or CFG values are not supported.
## What this is not
- Not a standalone model. It needs the `Qwen/Qwen-Image-2.1` base weights.
- Not a replacement for the base model when you need its full quality.
- Not a finished release. Expect the weights to change in future versions.
## License
The end distilled model is based on Qwen-Image-2.1.
P-Q-Image-2.1 is a derivative of Qwen-Image-2.1 and is distributed
under the **Qwen RESEARCH LICENSE AGREEMENT**. Review its use restrictions
before using or redistributing the adapters.
Qwen is licensed under the Qwen RESEARCH LICENSE AGREEMENT, Copyright (c) 2026
Hangzhou Tongyi Laboratory Technology Co., Ltd. All Rights Reserved.
## What's next?
- **Use P-Q-Image-2.1 to generate and edit images with Qwen-Image-2.1 in a few steps.**
- Compress your own models with [Pruna](https://github.com/PrunaAI/pruna) and give us a ⭐️ for more efficiency!
- Want to use our optimized image models right away? Check [P-Image-Ideogram](https://www.pruna.ai/p-image-ideogram) and [P-Image-Edit](https://www.pruna.ai/p-image-edit).
Try our models